Parameters
0.1K total / 0.0K active
MoE: total / active
Architecture
Causal Language Model
Released
30.01.2026
License
Apache License 2.0
Input Modalities
Output Modalities
Context (native)
262,144 tokens
Context (extended)
262,144 tokens
About
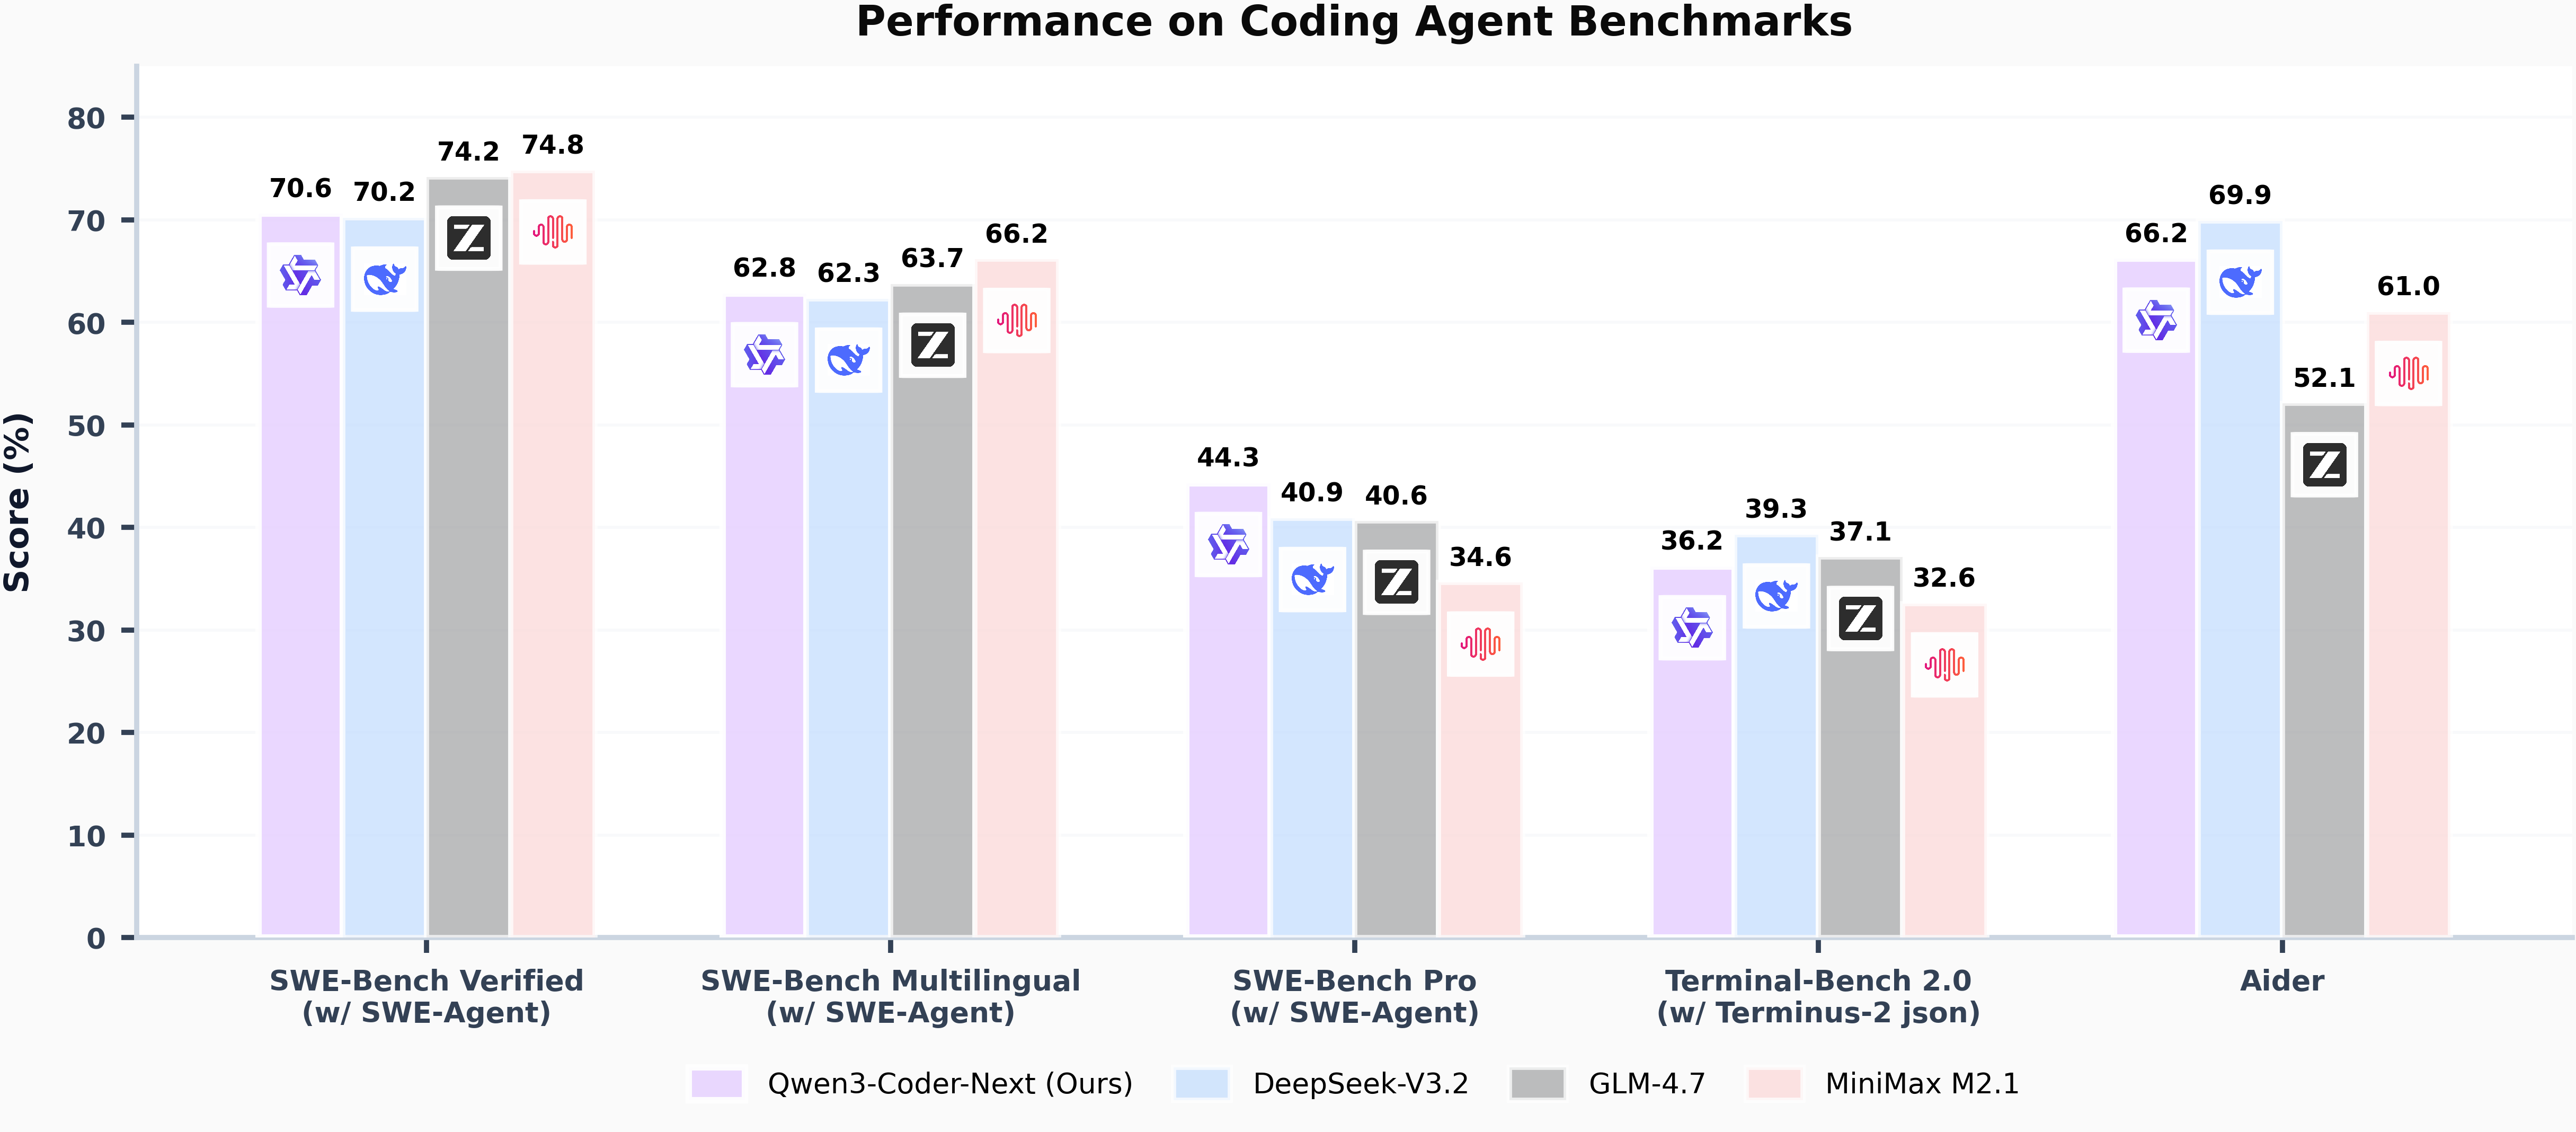
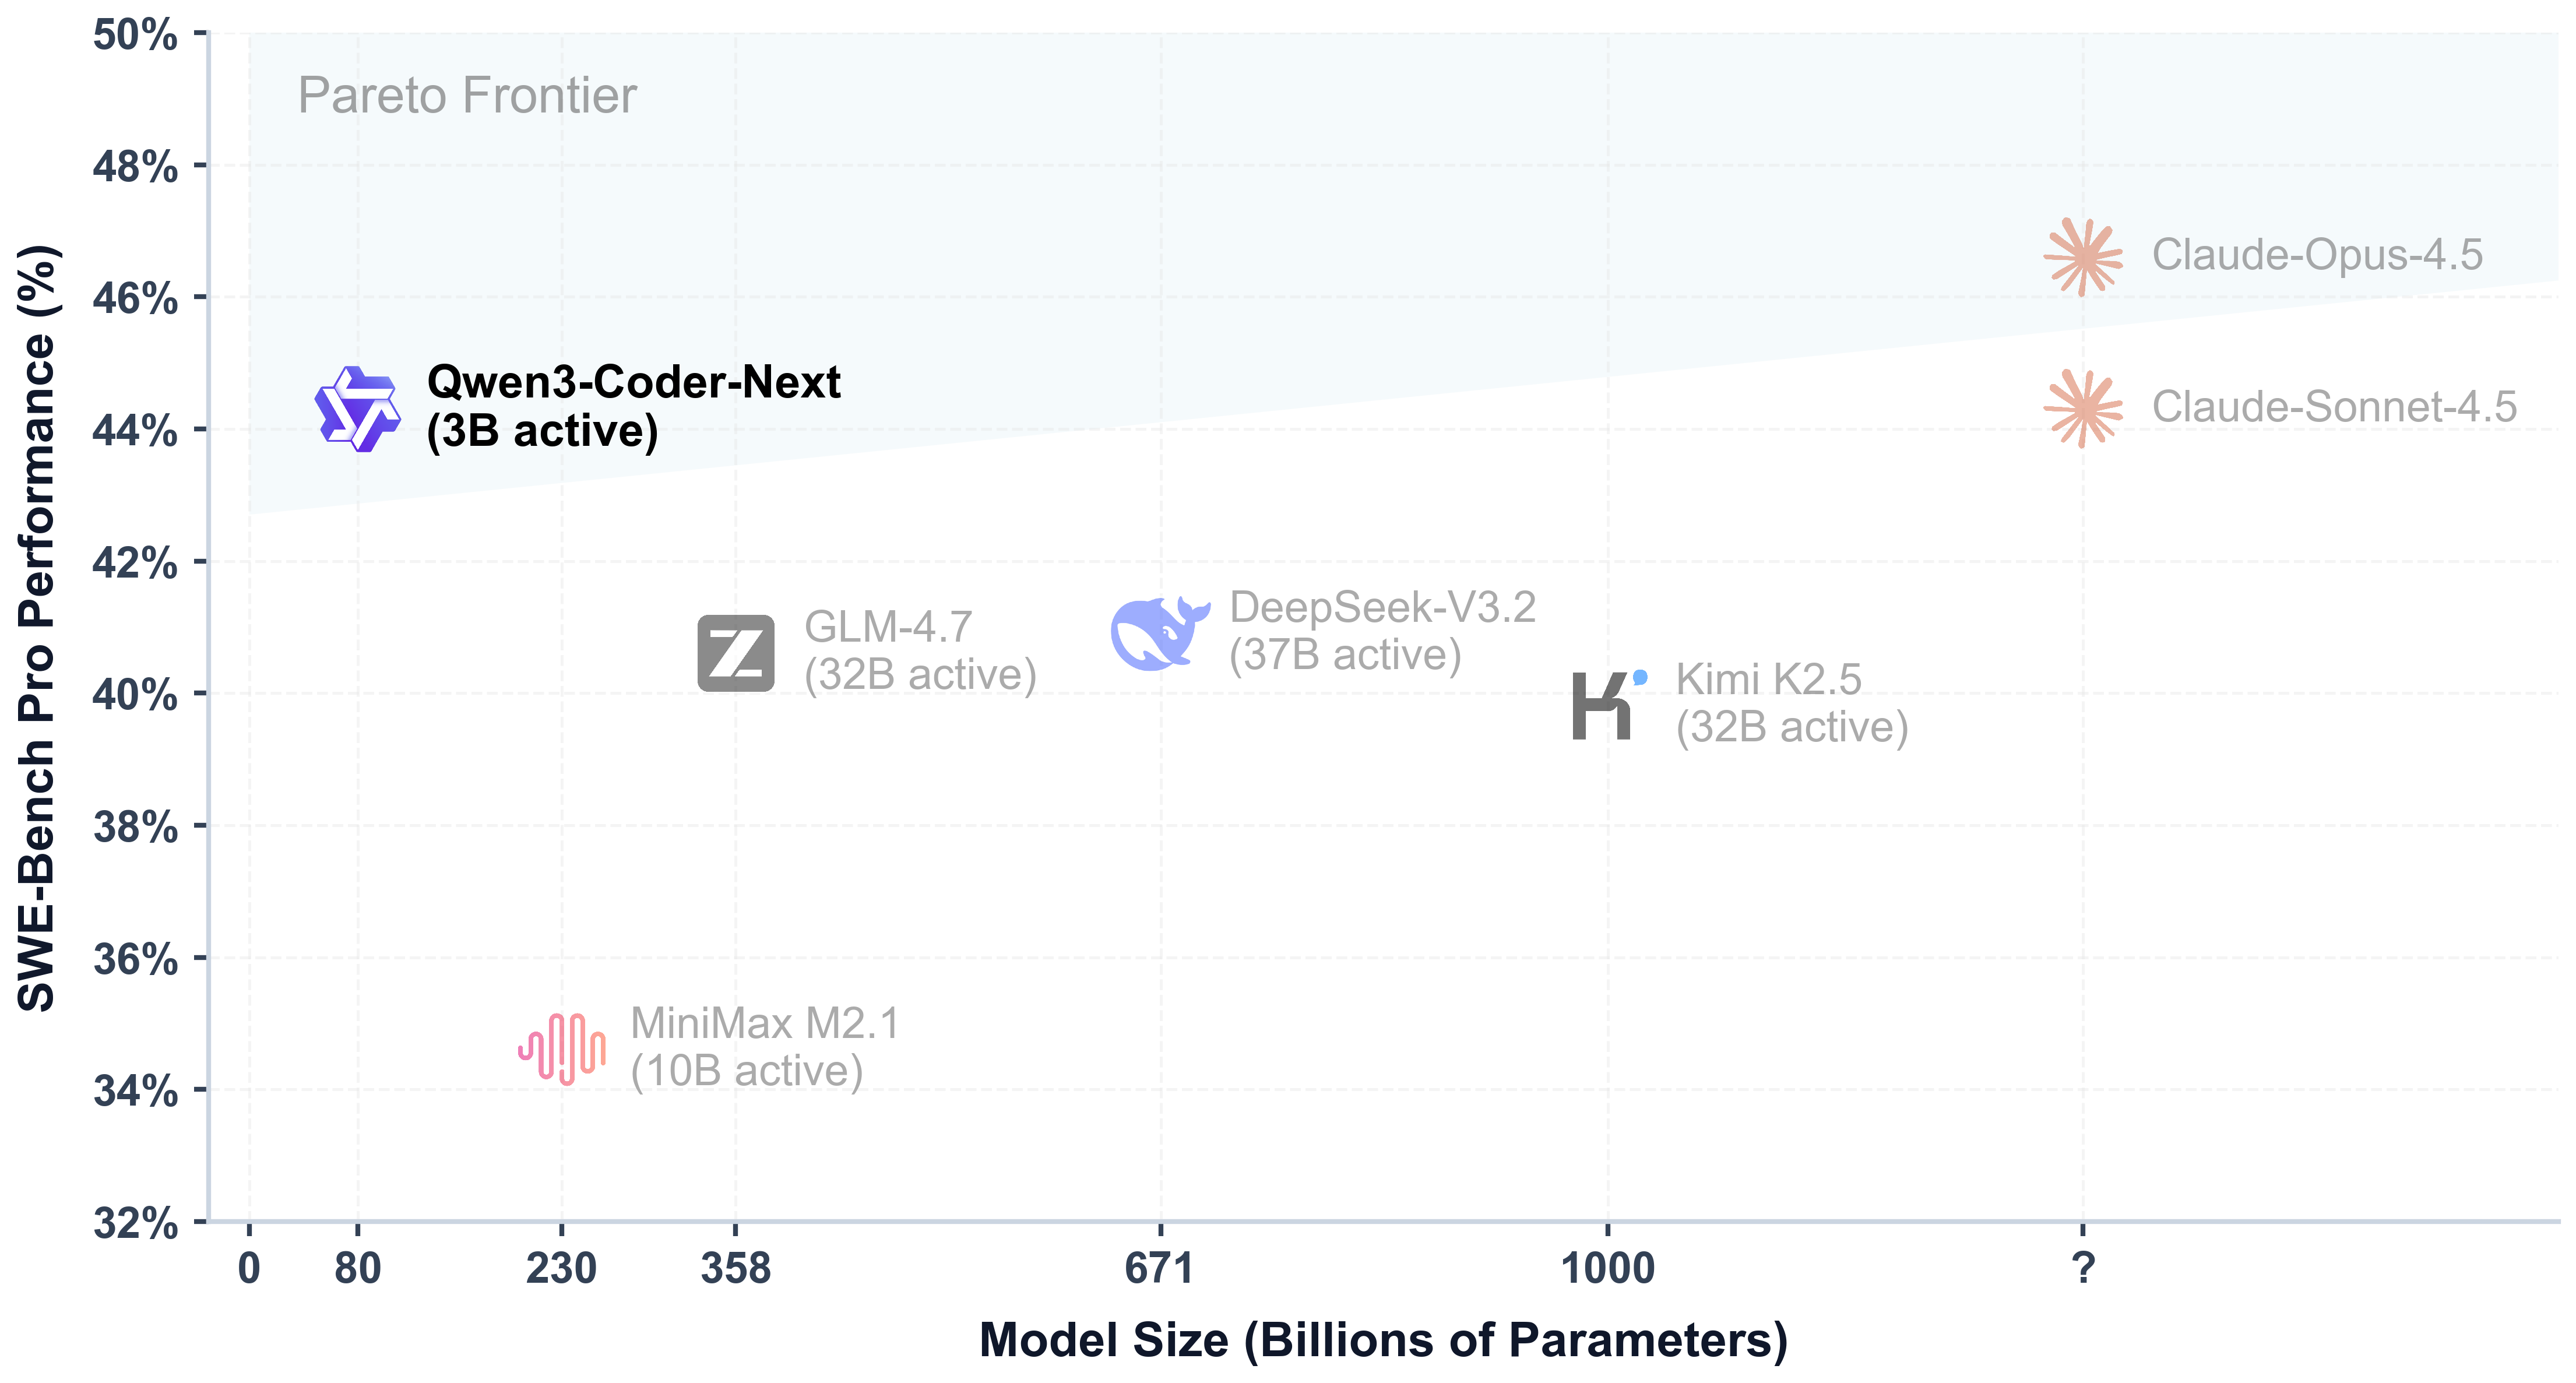
Qwen3-Coder-Next (Qwen/Qwen3-Coder-Next) is Alibaba's open-weight language model designed specifically for coding agents and local development - a sparse Mixture-of-Experts with 80B total parameters and only 3B activated (79B non-embedding), delivering performance comparable to models with 10-20x more active parameters at high cost-effectiveness for agent deployment.
Its 48-layer hybrid layout repeats 12x (3x (Gated DeltaNet -> MoE) + 1x (Gated Attention -> MoE)): 36 linear-attention layers (Gated DeltaNet with 32 V / 16 QK heads, head dim 128) and 12 full-attention layers (Gated Attention with 16 Q / 2 KV heads, head dim 256, RoPE dim 64), with hidden size 2048. The MoE uses 512 experts with 10 activated per token plus 1 shared expert (expert intermediate dim 512). Context length is 262,144 tokens natively.
Qwen3-Coder-Next excels at long-horizon reasoning, complex tool usage and recovery from execution failures via an elaborate agentic training recipe, and integrates seamlessly with real-world IDE/CLI scaffolds (Claude Code, Qwen Code, Qoder, Kilo, Trae, Cline and more). Note: it supports non-thinking mode only - it does not generate <think> blocks, and enable_thinking=False is no longer required. Released January 30, 2026 under Apache 2.0.
Training Data Pretraining & Post-training
Benchmark Scores
| Benchmark | Score | Date |
|---|---|---|
|
SWE-bench Verified
coding_agent
|
80.50%
|
03.02.2026 |
|
SWE-bench Pro
coding_agent
|
55.38%
|
03.02.2026 |
|
Terminal-Bench 2.0
coding_agent
|
11.75%
|
03.02.2026 |
|
Aider
coding_agent
|
79.21%
|
03.02.2026 |
|
SWE-bench Multilingual
coding_agent
|
68.40%
|
03.02.2026 |
Model Tree, Spaces and Collection
Citation
Citation
If you find our work helpful, feel free to give us a cite.
@techreport{qwen_qwen3_coder_next_tech_report,
  title        = {Qwen3-Coder-Next Technical Report},
  author       = {{Qwen Team}},
  url          = {https://github.com/QwenLM/Qwen3-Coder/blob/main/qwen3_coder_next_tech_report.pdf},
  note         = {Accessed: 2026-02-03}
}
Model size
80B params
Tensor type
BF16
·
Best Practices
Best Practices
To achieve optimal performance, we recommend the following sampling parameters: temperature=1.0, top_p=0.95, top_k=40.
Agentic Coding (tool use)
Agentic Coding
Qwen3-Coder-Next excels in tool calling capabilities.
You can simply define or use any tools as following example.
## Your tool implementation
def square_the_number(num: float) -> dict:
    return num ** 2

## Define Tools
tools=[
    {
        "type":"function",
        "function":{
            "name": "square_the_number",
            "description": "output the square of the number.",
            "parameters": {
                "type": "object",
                "required": ["input_num"],
                "properties": {
                    'input_num': {
                        'type': 'number',
                        'description': 'input_num is a number that will be squared'
                        }
                },
            }
        }
    }
]

from openai import OpenAI
## Define LLM
client = OpenAI(
    # Use a custom endpoint compatible with OpenAI API
    base_url='http://localhost:8000/v1',  # api_base
    api_key="EMPTY"
)

messages = [{'role': 'user', 'content': 'square the number 1024'}]

completion = client.chat.completions.create(
    messages=messages,
    model="Qwen3-Coder-Next",
    max_tokens=65536,
    tools=tools,
)

print(completion.choices[0])
Deployment (SGLang, vLLM)
Deployment
For deployment, you can use the latest sglang or vllm to create an OpenAI-compatible API endpoint.
SGLang
SGLang is a fast serving framework for large language models and vision language models. SGLang could be used to launch a server with OpenAI-compatible API service.
sglang>=v0.5.8 is required for Qwen3-Coder-Next, which can be installed using:
pip install 'sglang[all]>=v0.5.8'
See its documentation for more details.
The following command can be used to create an API endpoint at http://localhost:30000/v1 with maximum context length 256K tokens using tensor parallel on 4 GPUs.
python -m sglang.launch_server --model Qwen/Qwen3-Coder-Next --port 30000 --tp-size 2 --tool-call-parser qwen3_coder
The default context length is 256K. Consider reducing the context length to a smaller value, e.g.,
32768, if the server fails to start.
vLLM
vLLM is a high-throughput and memory-efficient inference and serving engine for LLMs. vLLM could be used to launch a server with OpenAI-compatible API service.
vllm>=0.15.0 is required for Qwen3-Coder-Next, which can be installed using:
pip install 'vllm>=0.15.0'
See its documentation for more details.
The following command can be used to create an API endpoint at http://localhost:8000/v1 with maximum context length 256K tokens using tensor parallel on 4 GPUs.
vllm serve Qwen/Qwen3-Coder-Next --port 8000 --tensor-parallel-size 2 --enable-auto-tool-choice --tool-call-parser qwen3_coder
The default context length is 256K. Consider reducing the context length to a smaller value, e.g.,
32768, if the server fails to start.
Quickstart (transformers)
Quickstart
We advise you to use the latest version of transformers.
The following contains a code snippet illustrating how to use the model generate content based on given inputs.
from transformers import AutoModelForCausalLM, AutoTokenizer

model_name = "Qwen/Qwen3-Coder-Next"

## load the tokenizer and the model
tokenizer = AutoTokenizer.from_pretrained(model_name)
model = AutoModelForCausalLM.from_pretrained(
  model_name,
  torch_dtype="auto",
  device_map="auto"
)

## prepare the model input
prompt = "Write a quick sort algorithm."
messages = [
  {"role": "user", "content": prompt}
]
text = tokenizer.apply_chat_template(
  messages,
  tokenize=False,
  add_generation_prompt=True,
)
model_inputs = tokenizer([text], return_tensors="pt").to(model.device)

## conduct text completion
generated_ids = model.generate(
    **model_inputs,
    max_new_tokens=65536
)
output_ids = generated_ids[0][len(model_inputs.input_ids[0]):].tolist()

content = tokenizer.decode(output_ids, skip_special_tokens=True)

print("content:", content)
Note: If you encounter out-of-memory (OOM) issues, consider reducing the context length to a shorter value, such as 32,768.
For local use, applications such as Ollama, LMStudio, MLX-LM, llama.cpp, and KTransformers have also supported Qwen3.
Model Overview (architecture)
Model Overview
Qwen3-Coder-Next has the following features:
- Type: Causal Language Models
- Training Stage: Pretraining & Post-training
- Number of Parameters: 80B in total and 3B activated
- Number of Parameters (Non-Embedding): 79B
- Hidden Dimension: 2048
- Number of Layers: 48
- Hybrid Layout: 12 * (3 * (Gated DeltaNet -> MoE) -> 1 * (Gated Attention -> MoE))
- Gated Attention:
- Number of Attention Heads: 16 for Q and 2 for KV
- Head Dimension: 256
- Rotary Position Embedding Dimension: 64
- Gated DeltaNet:
- Number of Linear Attention Heads: 32 for V and 16 for QK
- Head Dimension: 128
- Mixture of Experts:
- Number of Experts: 512
- Number of Activated Experts: 10
- Number of Shared Experts: 1
- Expert Intermediate Dimension: 512
- Context Length: 262,144 natively
NOTE: This model supports only non-thinking mode and does not generate <think></think> blocks in its output. Meanwhile, specifying enable_thinking=False is no longer required.
For more details, including benchmark evaluation, hardware requirements, and inference performance, please refer to our blog, GitHub, and Documentation.
Highlights (coding agents, local development)
Highlights
Today, we're announcing Qwen3-Coder-Next, an open-weight language model designed specifically for coding agents and local development. It features the following key enhancements:
- Super Efficient with Significant Performance: With only 3B activated parameters (80B total parameters), it achieves performance comparable to models with 10–20x more active parameters, making it highly cost-effective for agent deployment.
- Advanced Agentic Capabilities: Through an elaborate training recipe, it excels at long-horizon reasoning, complex tool usage, and recovery from execution failures, ensuring robust performance in dynamic coding tasks.
- Versatile Integration with Real-World IDE: Its 256k context length, combined with adaptability to various scaffold templates, enables seamless integration with different CLI/IDE platforms (e.g., Claude Code, Qwen Code, Qoder, Kilo, Trae, Cline, etc.), supporting diverse development environments.
Architecture
- Attention
- Hybrid Attention (16:2)
- MoE
- 512 experts · top-10 per token
- Layers
- 48
- Hidden size
- 2048
- Context
- 262K tokens
- RoPE θ
- 5M
- Parameters
- 80
- Active params
- 3
Source: Hugging Face config.json · Qwen3NextForCausalLM · exact layer pattern · model repo
Training Pipeline
-
1
pretraining
Pretraining
Pretraining stage with large-scale text and code corpora
-
2
other
Post-training
Post-training stage including elaborate training recipe for agentic capabilities, long-horizon reasoning, complex tool usage, and recovery from execution failures
Training & Evaluation Datasets
| Name | Role | Size | Modalities | Collection |
|---|---|---|---|---|
| Coding-agent training corpus (long-horizon agentic coding) | finetune | — | — |
Linked Resources
Qwen3-Coder-Next Blog
https://qwen.ai/blog?id=qwen3-coder-next
Qwen3-Coder GitHub Repository
https://github.com/QwenLM/Qwen3-Coder
Qwen3-Coder-Next Technical Report
https://github.com/QwenLM/Qwen3-Coder/blob/main/qwen3_coder_next_tech_report.pdf
Qwen3 Documentation
https://qwen.readthedocs.io/en/latest/
Trend Analysis
24h Change
+0.2%
7d Change
+1.9%
Current
101,994
downloads
+0.3%
likes
+0.0%
downloads_all_time
+0.2%
downloads
+0.0%
Usage & Social Metrics
| Source | Metric | Value | Period | Recorded |
|---|---|---|---|---|
| ollama | downloads | 2,000,000 pulls | daily | 01.09.2026 |
| huggingface | downloads_all_time | 6,365,348 | daily | 01.09.2026 |
| huggingface | followers | 101,994 | daily | 01.09.2026 |
| huggingface | likes | 1,622 | daily | 01.09.2026 |
| huggingface | downloads | 449,526 | daily | 01.09.2026 |
| ollama | downloads | 2,000,000 pulls | daily | 31.08.2026 |
| huggingface | downloads_all_time | 6,350,702 | daily | 31.08.2026 |
| huggingface | followers | 101,772 | daily | 31.08.2026 |
| huggingface | likes | 1,622 | daily | 31.08.2026 |
| huggingface | downloads | 447,978 | daily | 31.08.2026 |
| ollama | downloads | 2,000,000 pulls | daily | 30.08.2026 |
| huggingface | downloads_all_time | 6,340,611 | daily | 30.08.2026 |
| huggingface | followers | 101,528 | daily | 30.08.2026 |
| huggingface | likes | 1,622 | daily | 30.08.2026 |
| huggingface | downloads | 451,234 | daily | 30.08.2026 |
| ollama | downloads | 2,000,000 pulls | daily | 29.08.2026 |
| huggingface | followers | 101,306 | daily | 29.08.2026 |
| huggingface | likes | 1,622 | daily | 29.08.2026 |
| huggingface | downloads | 457,456 | daily | 29.08.2026 |
| ollama | downloads | 2,000,000 pulls | daily | 28.08.2026 |
| huggingface | followers | 101,117 | daily | 28.08.2026 |
| huggingface | likes | 1,620 | daily | 28.08.2026 |
| huggingface | downloads | 471,043 | daily | 28.08.2026 |
| ollama | downloads | 2,000,000 pulls | daily | 27.08.2026 |
| huggingface | followers | 100,862 | daily | 27.08.2026 |
| huggingface | likes | 1,617 | daily | 27.08.2026 |
| huggingface | downloads | 490,480 | daily | 27.08.2026 |
| ollama | downloads | 2,000,000 pulls | daily | 26.08.2026 |
| huggingface | followers | 100,537 | daily | 26.08.2026 |
| huggingface | likes | 1,616 | daily | 26.08.2026 |
| huggingface | downloads | 500,129 | daily | 26.08.2026 |
| ollama | downloads | 2,000,000 pulls | daily | 25.08.2026 |
| huggingface | followers | 100,133 | daily | 25.08.2026 |
| huggingface | likes | 1,615 | daily | 25.08.2026 |
| huggingface | downloads | 503,858 | daily | 25.08.2026 |
| ollama | downloads | 2,000,000 pulls | daily | 24.08.2026 |
| huggingface | followers | 99,896 | daily | 24.08.2026 |
| huggingface | likes | 1,614 | daily | 24.08.2026 |
| huggingface | downloads | 507,586 | daily | 24.08.2026 |
| huggingface | followers | 99,669 | daily | 23.08.2026 |
| huggingface | likes | 1,613 | daily | 23.08.2026 |
| huggingface | downloads | 509,562 | daily | 23.08.2026 |
| huggingface | followers | 99,461 | daily | 22.08.2026 |
| huggingface | likes | 1,611 | daily | 22.08.2026 |
| huggingface | downloads | 513,767 | daily | 22.08.2026 |
| huggingface | followers | 99,274 | daily | 21.08.2026 |
| huggingface | likes | 1,610 | daily | 21.08.2026 |
| huggingface | downloads | 517,055 | daily | 21.08.2026 |
| huggingface | followers | 99,037 | daily | 20.08.2026 |
| huggingface | likes | 1,608 | daily | 20.08.2026 |