Parameters
30.0B total / 3.0B active
MoE: total / active
Architecture
Mixture-of-Experts Vision-Language Transformer
Released
04.10.2025
License
Apache License 2.0
Input Modalities
Output Modalities
Context (native)
262,144 tokens
Context (extended)
1,000,000 tokens
About
Qwen3-VL-30B-A3B (Instruct) is the MoE vision-language model of the Qwen3-VL series, the most powerful VLM family the Qwen team (Alibaba) has released to date. It pairs a Qwen3-ViT vision encoder (initialized from SigLIP-2 SO-400M and continued on dynamic resolutions with 2D-RoPE) with the Qwen3-30B-A3B MoE LLM backbone (30B total, 3B activated per token, 128 experts with 8 routed per token), a two-layer MLP vision-language merger that compresses 2x2 visual features into one visual token, and DeepStack fusion of multi-level ViT features.
Its defining novelties are Interleaved-MRoPE (redesigned multimodal RoPE that interleaves temporal/height/width frequency components for long-horizon video reasoning) and Text-Timestamp Alignment, which moves beyond T-RoPE to precise, timestamp-grounded event localization for video temporal modeling. Key capabilities: a Visual Agent that operates PC/mobile GUIs, visual coding (Draw.io/HTML/CSS/JS from images and videos), advanced spatial perception with 2D/3D grounding, native 256K context expandable to 1M, hours-long video understanding with second-level indexing, OCR in 32 languages, and multimodal STEM/Math reasoning. Text understanding is on par with pure LLMs. Pre-training spans vision-language alignment (67B tokens), ~2T multimodal/long-context tokens and 100B ultra-long-context tokens; post-training uses SFT, strong-to-weak distillation and RL. Maintained by the Qwen team; Apache-2.0 weights on HuggingFace and Ollama; serves English, Chinese and more (32 OCR languages, multilingual benchmarks).
Training Data Pre-training: VL alignment (67B tokens) -> multimodal pre-training (~1T, 8K seq) -> long-context pre-training (~1T, 32K seq) -> ultra-long-context adaptation (100B, 256K seq). Post-training: SFT -> strong-to-weak distillation (text-only) -> RL (Reasoning RL + General RL).
Benchmark Scores
| Benchmark | Score | Date |
|---|---|---|
|
MMLU-Pro
knowledge
|
57.42%
|
04.10.2025 |
|
MMLU-Redux
knowledge
|
69.75%
|
04.10.2025 |
|
GPQA
reasoning
|
89.07%
|
04.10.2025 |
|
SuperGPQA
knowledge
|
60.59%
|
04.10.2025 |
|
AIME 2025
stem_reasoning
|
63.12%
|
04.10.2025 |
|
HMMT Feb 25
stem_reasoning
|
1.78%
|
04.10.2025 |
|
LiveBench 241125
reasoning
|
65.40
|
04.10.2025 |
|
IFEval
instruction_following
|
84.72%
|
04.10.2025 |
|
Arena-Hard v2
instruction_following
|
58.50
|
04.10.2025 |
|
Creative Writing v3
instruction_following
|
100.00%
|
04.10.2025 |
|
WritingBench
instruction_following
|
82.60
|
04.10.2025 |
|
LiveCodeBench v6
stem_reasoning
|
30.56%
|
04.10.2025 |
|
BFCL-V3
general_agent
|
66.30
|
04.10.2025 |
|
Multi-IF
instruction_following
|
68.80%
|
04.10.2025 |
|
MMLU-ProX
multilingual
|
70.90
|
04.10.2025 |
|
PolyMATH
multilingual
|
44.30
|
04.10.2025 |
|
INCLUDE
multilingual
|
4.65%
|
04.10.2025 |
Model Tree, Spaces and Collection
Model tree for Qwen/Qwen3-VL-30B-A3B-Instruct: 64 Spaces use this model. Part of the Qwen3-VL collection. Papers: Qwen3 Technical Report, Qwen2.5-VL Technical Report, Qwen2-VL, Qwen-VL.
Citation (Qwen Team, 2025)
Quickstart: Transformers Chat
Model Performance: Multimodal and Pure Text Tables (images)
The card presents performance as two image tables: Multimodal performance and Pure text performance (VL table, text table).
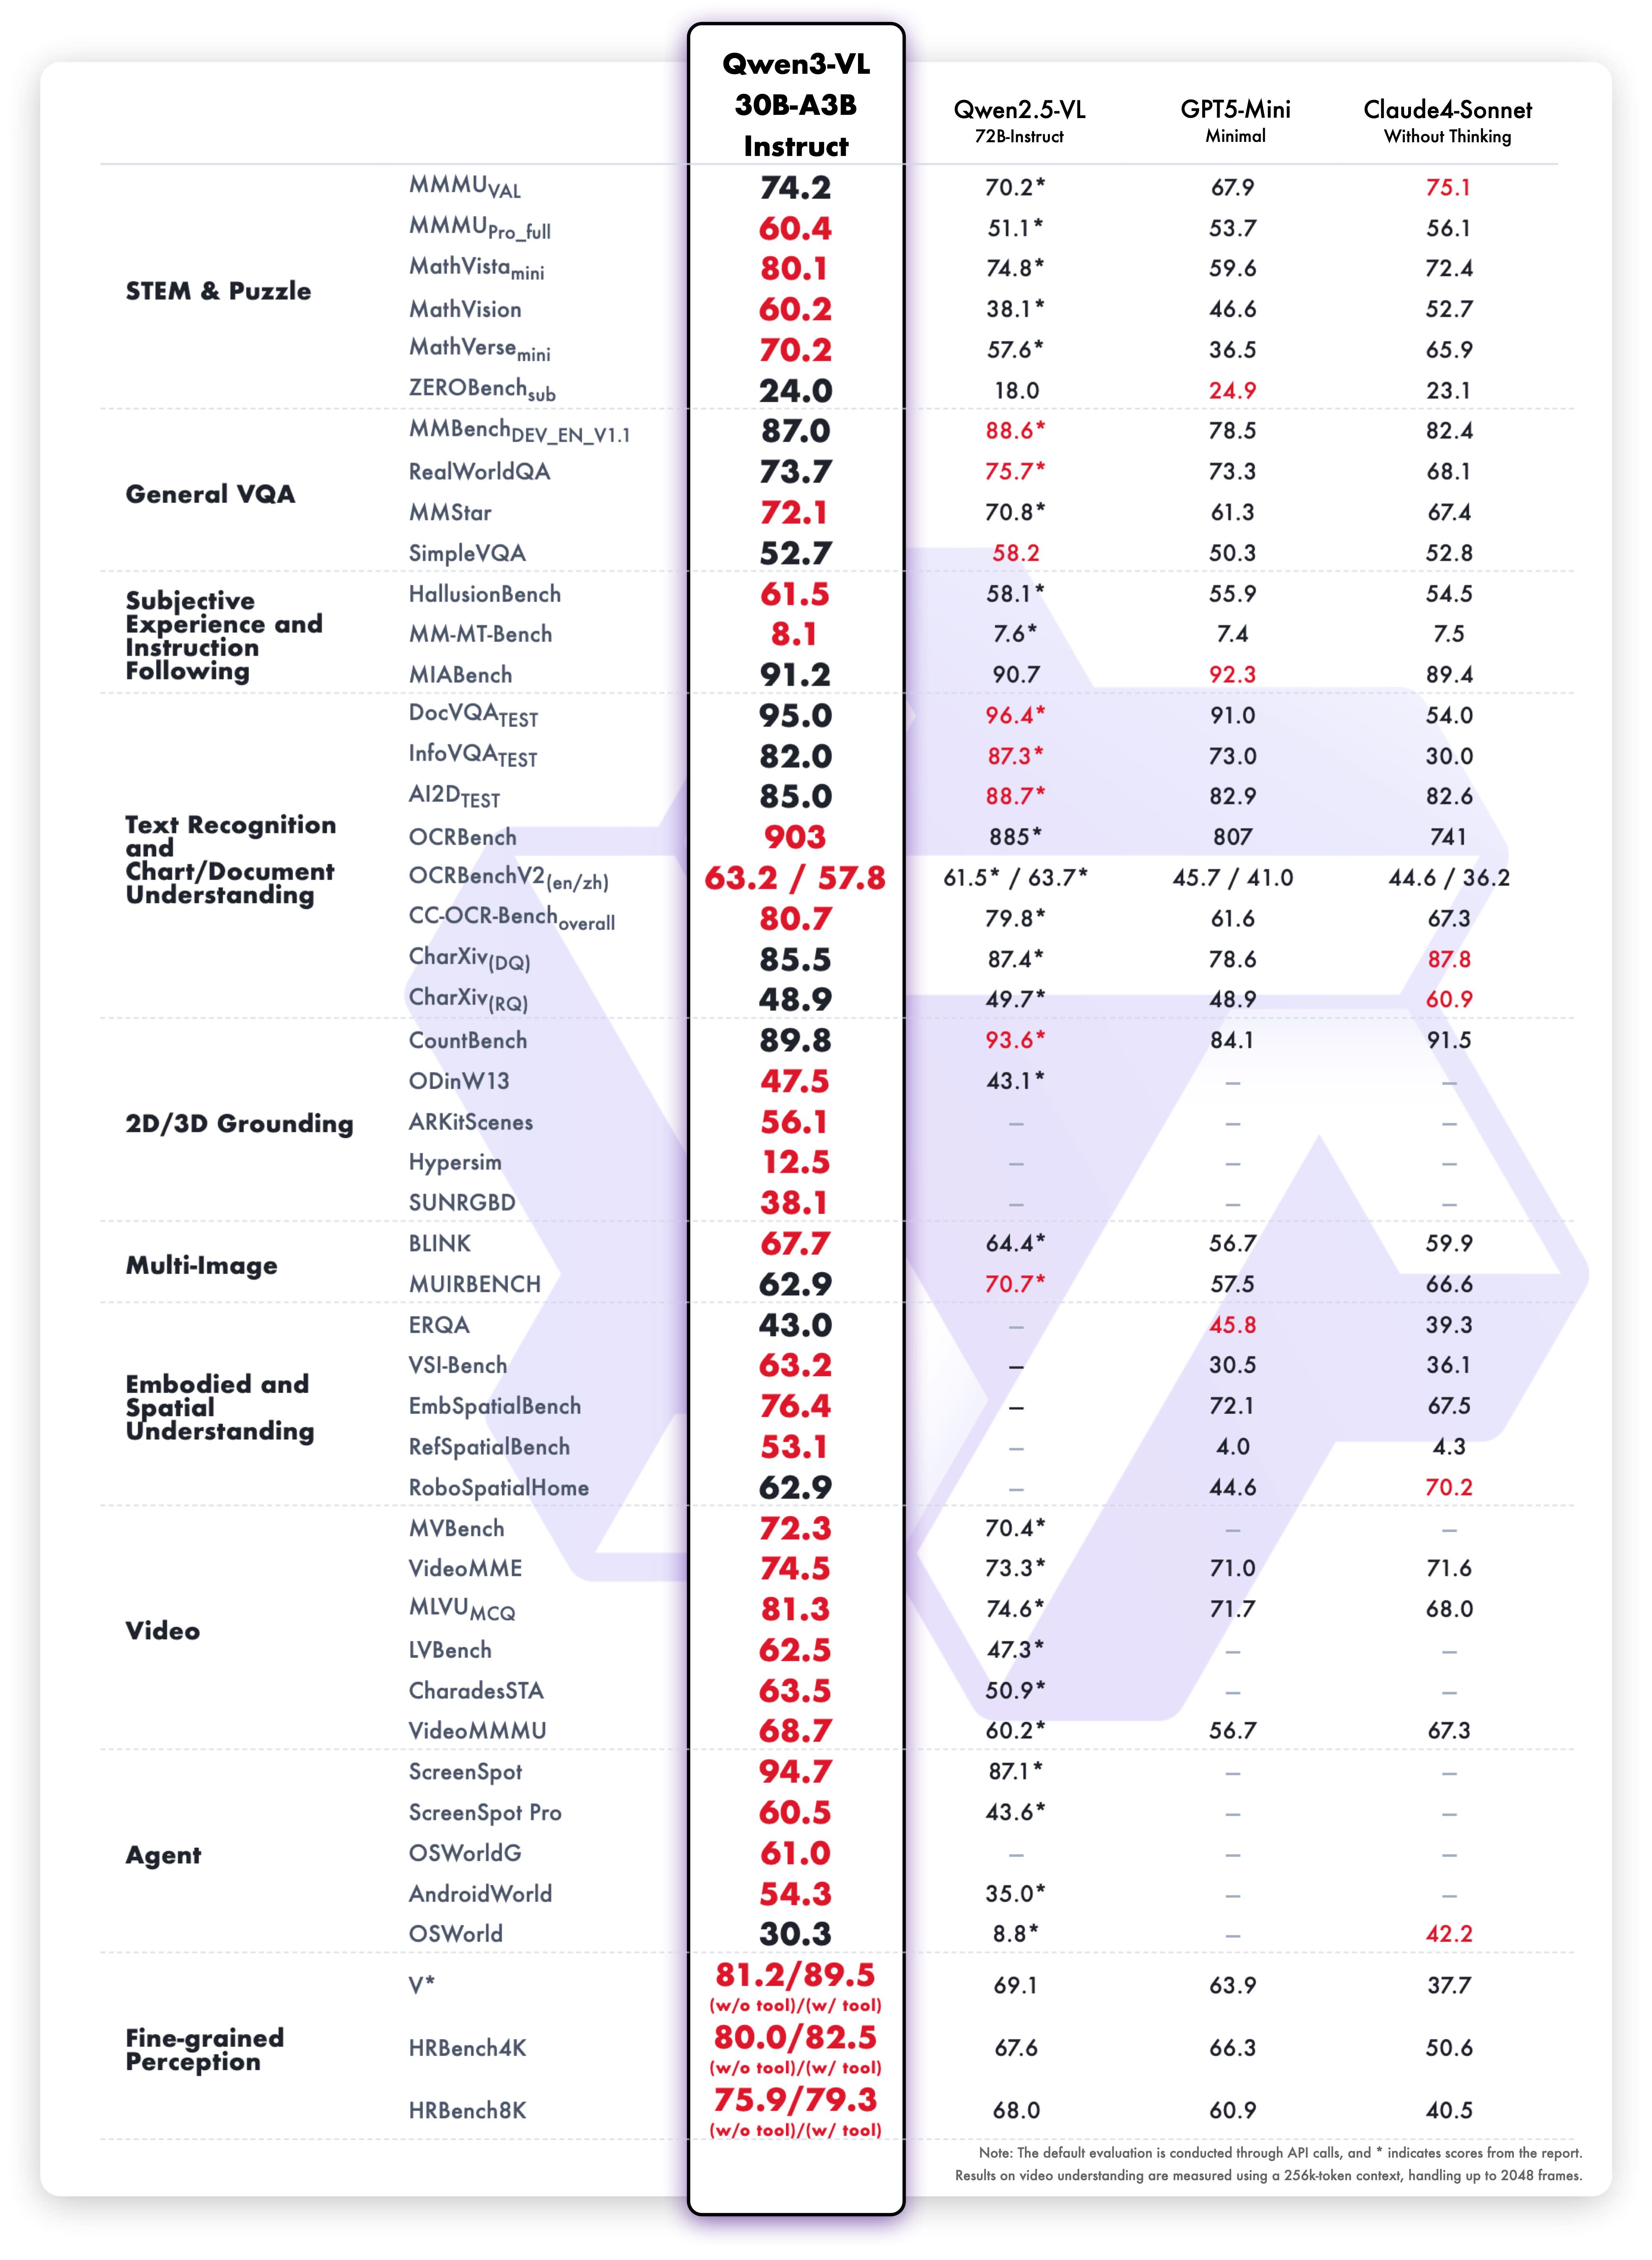
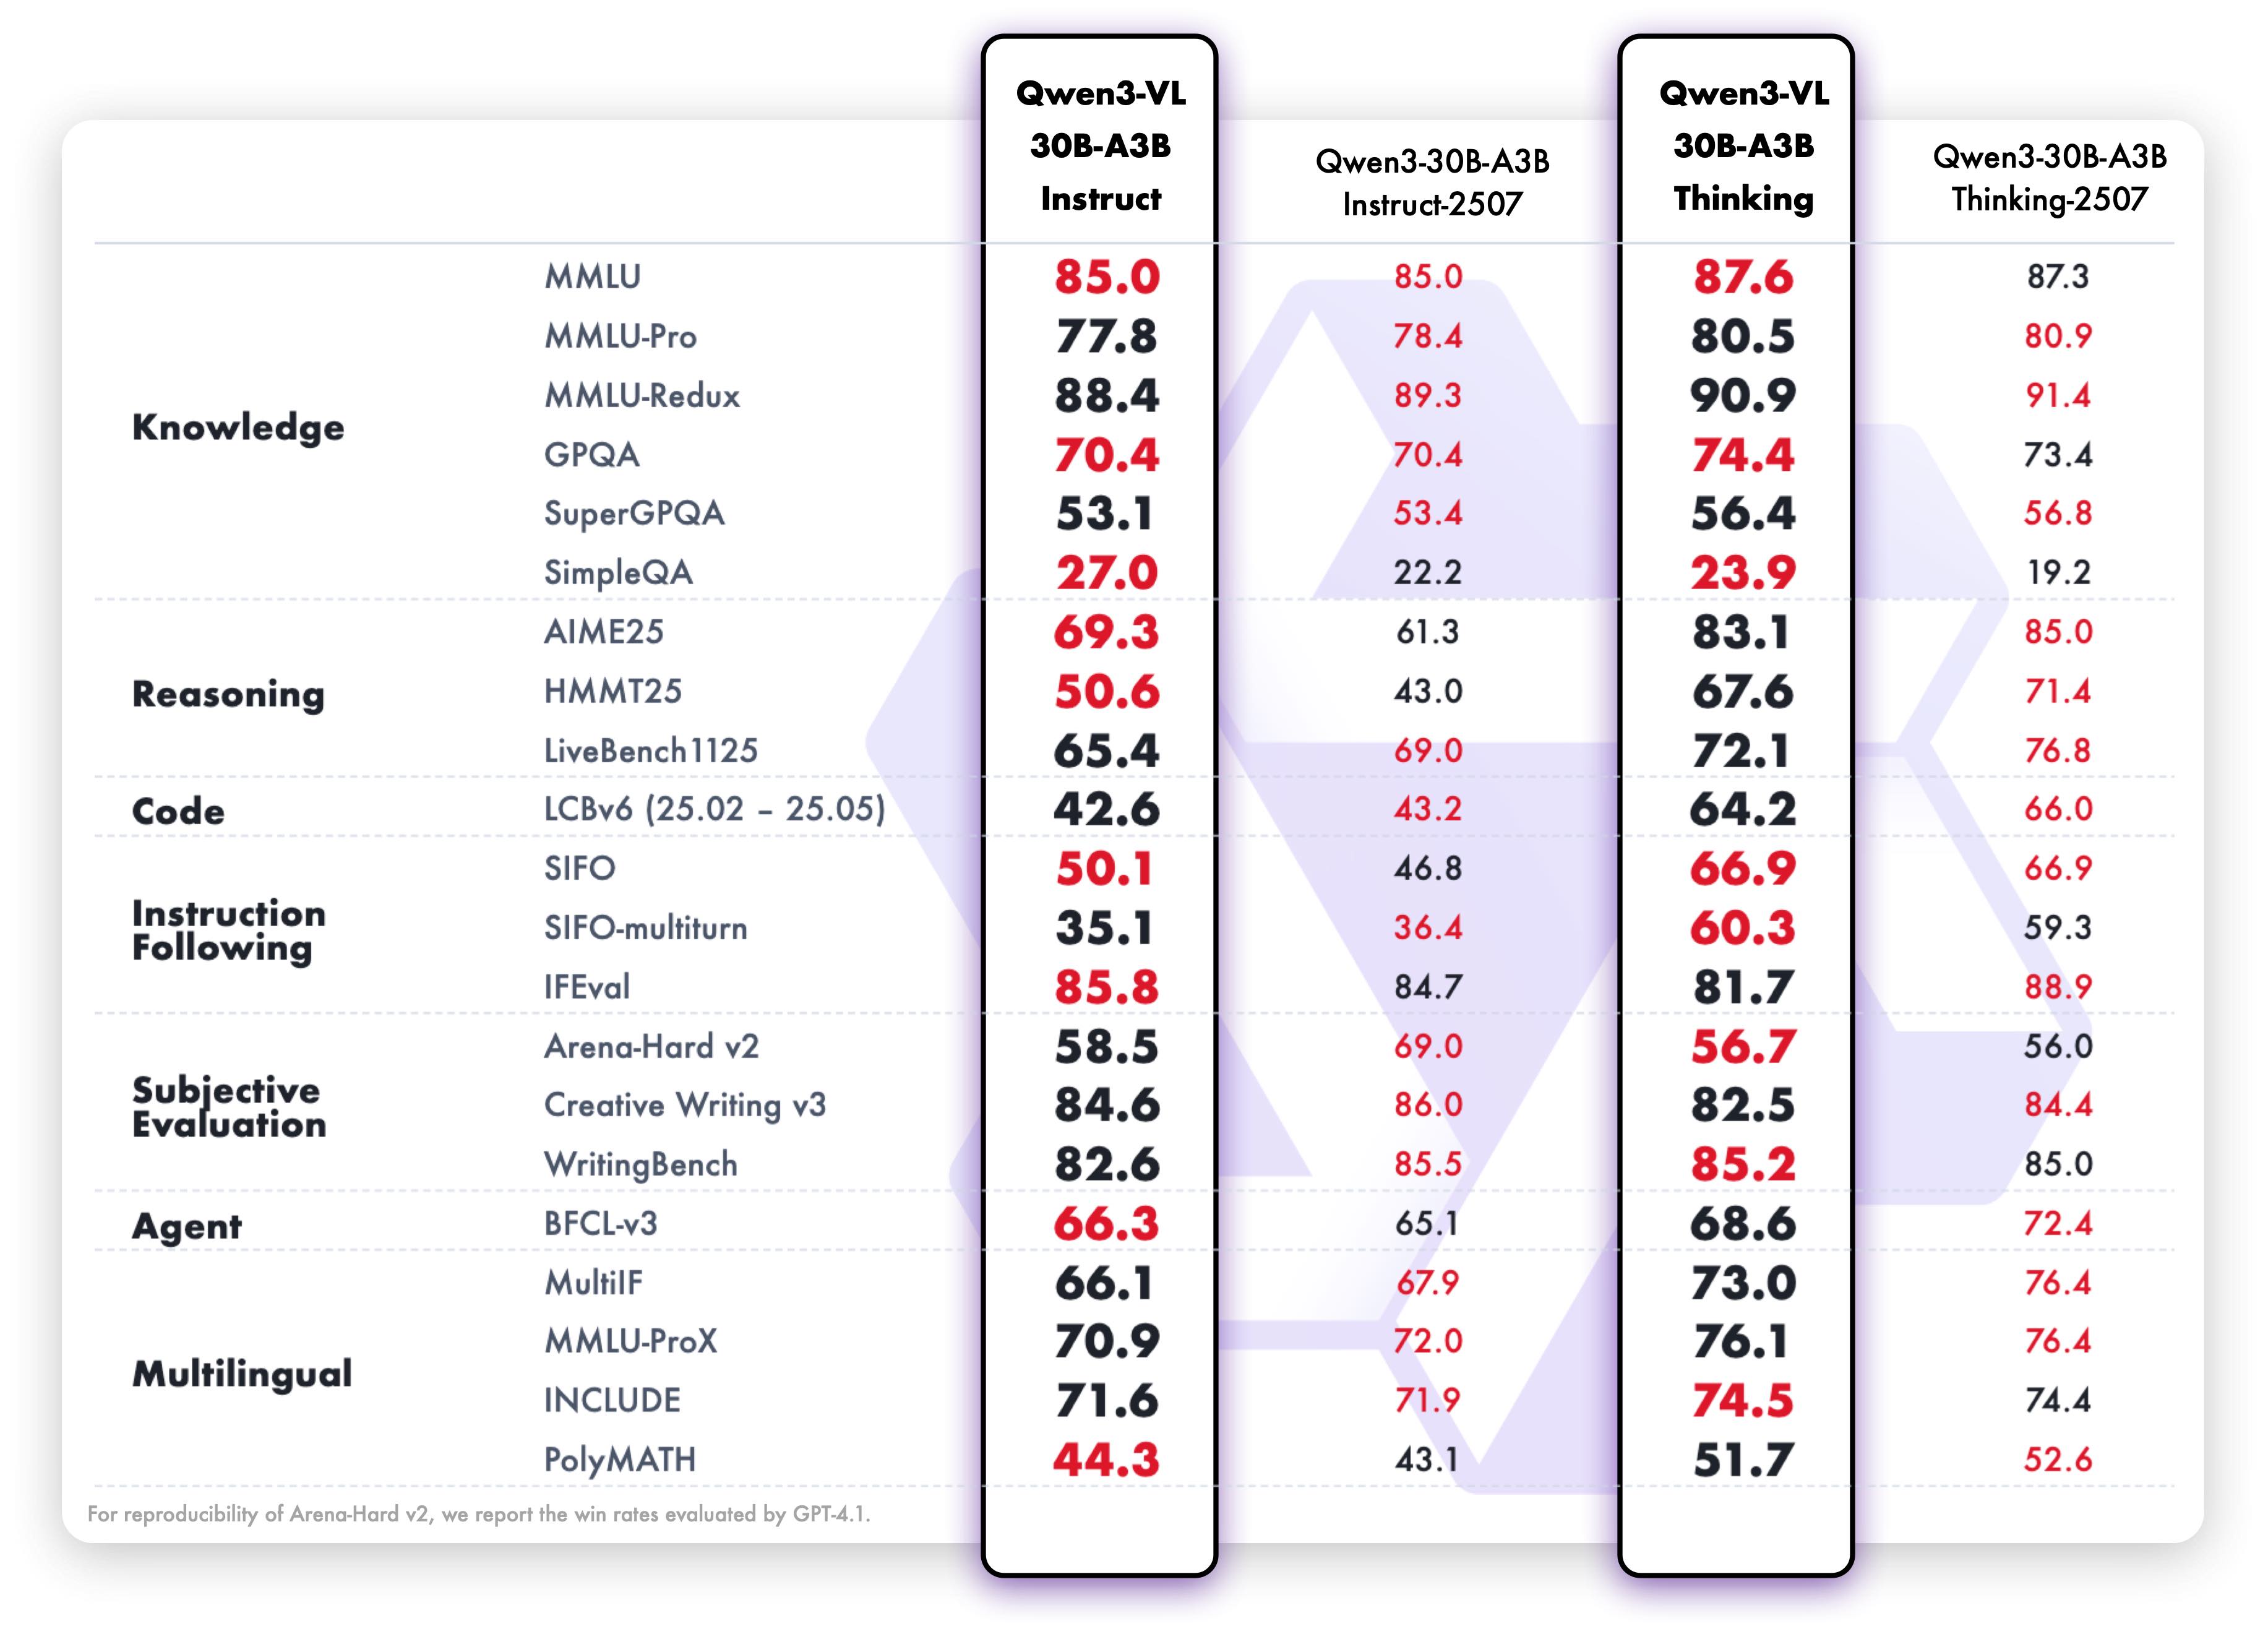
Text-centric scores are published in the Qwen3-VL Technical Report (Table 4): MMLU-Pro 77.8, MMLU-Redux 88.4, GPQA 70.4, SuperGPQA 53.1, AIME-25 69.3, HMMT-25 50.6, LiveBench 65.4, IFEval 85.8, Arena-Hard V2 58.5, Creative Writing v3 84.6, WritingBench 82.6, LiveCodeBench v6 42.6, BFCL-v3 66.3, MultiIF 66.1, MMLU-ProX 70.9, INCLUDE 71.6, PolyMATH 44.3.
Model Architecture Updates: Interleaved-MRoPE, DeepStack, Text-Timestamp Alignment
Key Enhancements: Visual Agent, Visual Coding, Spatial Perception, Long Context, Multimodal Reasoning, OCR
Architecture
- Attention
- Grouped Query Attention (32:4)
- MoE
- 128 experts · top-8 per token
- Layers
- 48
- Hidden size
- 2048
- Context
- 262K tokens
- RoPE θ
- 5M
- Parameters
- 30000M
- Active params
- 3000M
Source: Hugging Face config.json · Qwen3VLMoeForConditionalGeneration · model repo
Training Pipeline
-
1
other
S0: Vision-Language Alignment
Trains the merger on 67B tokens at sequence length 8,192 (Qwen3-VL TR Table 1).
-
2
pretraining
S1: Multimodal Pre-Training
All parameters on ~1T tokens at sequence length 8,192 (Qwen3-VL TR Table 1).
-
3
cpt
S2: Long-Context Pre-Training
All parameters on ~1T tokens at sequence length 32,768 (Qwen3-VL TR Table 1).
-
4
cpt
S3: Ultra-Long-Context Adaptation
All parameters on 100B tokens at sequence length 262,144 (Qwen3-VL TR Table 1).
-
5
sft
Supervised Fine-Tuning (32K then 256K context)
Instruction-following SFT in two phases: 32K context, then extension to 256K with long-document and long-video data; standard formats for non-thinking models, CoT formats for thinking models.
-
6
other
Strong-to-Weak Distillation
Knowledge distillation from a powerful teacher to the student models using text-only data to fine-tune the LLM backbone.
-
7
rl
RL: Reasoning RL + General RL
Large-scale RL across text and multimodal domains incl. math, OCR, grounding, instruction-following.
Training & Evaluation Datasets
| Name | Role | Size | Modalities | Collection |
|---|---|---|---|---|
| Image-caption pairs (Chinese-English web) | pretraining | — | — | |
| Interleaved text-image documents | pretraining | — | — | |
| OCR / document parsing data | pretraining | — | — | |
| Video data | pretraining | — | — | |
| Agent data | pretraining | — | — |
Linked Resources
Qwen3-VL Technical Report
https://arxiv.org/abs/2511.21631
Qwen3 Technical Report
https://arxiv.org/abs/2505.09388
Qwen2.5-VL Technical Report
https://arxiv.org/abs/2502.13923
QwenLM/Qwen3-VL repository
https://github.com/QwenLM/Qwen3-VL
Qwen3-VL HuggingFace collection
https://huggingface.co/collections/Qwen/qwen3-vl
Qwen Chat
https://chat.qwen.ai/
BibTeX citation (Qwen Team, 2025)
https://huggingface.co/Qwen/Qwen3-VL-30B-A3B-Instruct
Trend Analysis
24h Change
+0.2%
Current
101,994
downloads
+1.8%
downloads
+0.7%
downloads_all_time
+0.1%
likes
+0.0%
Usage & Social Metrics
| Source | Metric | Value | Period | Recorded |
|---|---|---|---|---|
| ollama | downloads | 5,600,000 pulls | daily | 01.09.2026 |
| huggingface | downloads_all_time | 17,579,560 | daily | 01.09.2026 |
| huggingface | followers | 101,994 | daily | 01.09.2026 |
| huggingface | likes | 595 | daily | 01.09.2026 |
| huggingface | downloads | 414,165 | daily | 01.09.2026 |
| ollama | downloads | 5,500,000 pulls | daily | 31.08.2026 |
| huggingface | downloads_all_time | 17,569,094 | daily | 31.08.2026 |
| huggingface | followers | 101,772 | daily | 31.08.2026 |
| huggingface | likes | 595 | daily | 31.08.2026 |
| huggingface | downloads | 411,404 | daily | 31.08.2026 |
| ollama | downloads | 5,500,000 pulls | daily | 30.08.2026 |
| huggingface | downloads_all_time | 17,563,211 | daily | 30.08.2026 |
| huggingface | followers | 101,528 | daily | 30.08.2026 |
| huggingface | likes | 595 | daily | 30.08.2026 |
| huggingface | downloads | 414,336 | daily | 30.08.2026 |
| ollama | downloads | 5,500,000 pulls | daily | 29.08.2026 |
| ollama | downloads | 5,500,000 pulls | daily | 28.08.2026 |
| ollama | downloads | 5,500,000 pulls | daily | 27.08.2026 |
| ollama | downloads | 5,500,000 pulls | daily | 26.08.2026 |
| ollama | downloads | 5,400,000 pulls | daily | 25.08.2026 |
| ollama | downloads | 5,400,000 pulls | daily | 24.08.2026 |