Parameters
27.0B
Architecture
Hybrid Gated DeltaNet + Gated Attention (dense)
Released
21.04.2026
License
Apache License 2.0
Input Modalities
Output Modalities
Context (native)
262,144 tokens
Context (extended)
1,010,000 tokens
About
Qwen3.6-27B (Qwen/Qwen3.6-27B) is the dense mid-size multimodal model of Alibaba's Qwen3.6 line - 27B parameters (dense; FFN-based, no MoE) handling text, image and video input. Its 64-layer hybrid stack repeats 16x (3x (Gated DeltaNet -> FFN) + 1x (Gated Attention -> FFN)): 48 linear-attention layers (Gated DeltaNet, 48 V / 16 QK heads, head dim 128) and 16 full-attention layers (Gated Attention, 24 Q / 4 KV heads, head dim 256, RoPE dim 64), with hidden size 5120, FFN intermediate dimension 17408, 248K vocabulary, Multi-Token Prediction (MTP) trained with multi-steps, and a 262,144-token native context extensible to 1,010,000.
The Qwen3.6 release delivers substantial upgrades in agentic coding - frontend workflows and repository-level reasoning with greater fluency and precision - and introduces thinking preservation, a new option to retain reasoning context from historical messages that streamlines iterative development and reduces overhead. Released April 21, 2026 under Apache 2.0.
Training Data Pre-training & Post-training. Trained with multi-token prediction (MTP) steps. Post-trained with Thinking Preservation feature.
Benchmark Scores
| Benchmark | Score | Date |
|---|---|---|
|
SWE-bench Verified
coding_agent
|
88.07%
|
22.04.2026 |
|
SWE-bench Pro
coding_agent
|
66.88%
|
22.04.2026 |
|
SWE-bench Multilingual
coding_agent
|
78.46%
|
22.04.2026 |
|
Terminal-Bench 2.0
coding_agent
|
74.86%
|
22.04.2026 |
|
SkillsBench Avg5
coding_agent
|
70.30%
|
22.04.2026 |
|
QwenWebBench
coding_agent
|
91.22%
|
22.04.2026 |
|
NL2Repo
coding_agent
|
39.85%
|
22.04.2026 |
|
Claw-Eval Avg
coding_agent
|
87.45%
|
22.04.2026 |
|
Claw-Eval Pass^3
coding_agent
|
78.41%
|
22.04.2026 |
|
QwenClawBench
coding_agent
|
100.00%
|
22.04.2026 |
|
MMLU-Pro
knowledge
|
84.52%
|
22.04.2026 |
|
MMLU-Redux
knowledge
|
91.18%
|
22.04.2026 |
|
SuperGPQA
knowledge
|
89.64%
|
22.04.2026 |
|
GPQA Diamond
stem_reasoning
|
87.71%
|
22.04.2026 |
|
Humanity's Last Exam
stem_reasoning
|
41.48%
|
22.04.2026 |
|
LiveCodeBench v6
stem_reasoning
|
86.90%
|
22.04.2026 |
|
HMMT Feb 25
stem_reasoning
|
97.78%
|
22.04.2026 |
|
HMMT Nov 25
stem_reasoning
|
70.56%
|
22.04.2026 |
|
HMMT Feb 26
stem_reasoning
|
82.64%
|
22.04.2026 |
|
IMOAnswerBench
stem_reasoning
|
82.67%
|
22.04.2026 |
|
AIME 26
stem_reasoning
|
93.49%
|
22.04.2026 |
|
MMMU
vision_language
|
95.41%
|
22.04.2026 |
|
MMMU-Pro
vision_language
|
80.61%
|
22.04.2026 |
|
MathVista (mini)
vision_language
|
95.40%
|
22.04.2026 |
|
DynaMath
vision_language
|
76.40%
|
22.04.2026 |
|
VlmsAreBlind
vision_language
|
100.00%
|
22.04.2026 |
|
RealWorldQA
vision_language
|
89.77%
|
22.04.2026 |
|
MMStar
vision_language
|
77.36%
|
22.04.2026 |
|
MMBench EN-DEV v1.1
vision_language
|
91.67%
|
22.04.2026 |
|
SimpleVQA
vision_language
|
53.59%
|
22.04.2026 |
|
CharXiv (RQ)
document_understanding
|
49.01%
|
22.04.2026 |
|
CC-OCR
document_understanding
|
94.24%
|
22.04.2026 |
|
OCRBench
document_understanding
|
82.58%
|
22.04.2026 |
|
ERQA
spatial_intelligence
|
68.89%
|
22.04.2026 |
|
CountBench
spatial_intelligence
|
100.00%
|
22.04.2026 |
|
RefCOCO (avg)
spatial_intelligence
|
100.00%
|
22.04.2026 |
|
EmbSpatialBench
spatial_intelligence
|
100.00%
|
22.04.2026 |
|
RefSpatialBench
spatial_intelligence
|
100.00%
|
22.04.2026 |
|
VideoMME (w sub.)
video_understanding
|
81.30%
|
22.04.2026 |
|
VideoMMMU
video_understanding
|
74.64%
|
22.04.2026 |
|
MLVU
video_understanding
|
95.17%
|
22.04.2026 |
|
MVBench
video_understanding
|
79.81%
|
22.04.2026 |
|
V-Star
vision_language
|
90.70%
|
22.04.2026 |
|
AndroidWorld
general_agent
|
45.17%
|
22.04.2026 |
|
Terminal-Bench 2.1 (Terminus-2)
coding_agent
|
62.54%
|
18.08.2026 |
|
IFBench (prompt loose)
instruction_following
|
33.85%
|
18.08.2026 |
|
OmniDocBench 1.5
document_understanding
|
97.59%
|
18.08.2026 |
|
DeepSWE 1.1
coding_agent
|
8.01%
|
18.08.2026 |
|
QwenSWEBench
coding_agent
|
49.30
|
18.08.2026 |
|
CoWorkBench
general_agent
|
51.62%
|
18.08.2026 |
|
JobBench
general_agent
|
21.80
|
18.08.2026 |
|
OSWorld-Verified
general_agent
|
57.52%
|
18.08.2026 |
|
RecreationBench
general_agent
|
29.80
|
18.08.2026 |
|
SWE-MM
coding_agent
|
25.70
|
18.08.2026 |
|
Vision2Web
vision_language
|
13.24%
|
18.08.2026 |
|
MathVision
vision_language
|
75.48%
|
18.08.2026 |
|
BabyVision
vision_language
|
21.17%
|
18.08.2026 |
|
MCP-Atlas
general_agent
|
68.26%
|
01.08.2026 |
|
DeepSearch QA
general_agent
|
28.23%
|
01.08.2026 |
|
TauBench V3 Banking
general_agent
|
18.93%
|
01.08.2026 |
|
WildClawBench
coding_agent
|
56.91%
|
01.08.2026 |
|
GDPVal-AA v2
general_agent
|
62.32%
|
01.08.2026 |
|
Gaia2
general_agent
|
21.70%
|
01.08.2026 |
|
SkillsBench
general_agent
|
34.55%
|
01.08.2026 |
|
SciCode (subtask)
stem_reasoning
|
7.28%
|
01.08.2026 |
|
ScreenSpot Pro
general_agent
|
100.00%
|
01.08.2026 |
|
IFBench
instruction_following
|
80.03%
|
01.08.2026 |
|
AA-LCR
long_context
|
91.62%
|
01.08.2026 |
|
Beam128K
long_context
|
69.57%
|
01.08.2026 |
|
MBCT
safety
|
25.29%
|
01.08.2026 |
|
HPCT
safety
|
48.70
|
01.08.2026 |
|
VCT
safety
|
33.70
|
01.08.2026 |
|
WMDP (Bio)
safety
|
84.80
|
01.08.2026 |
|
WMDP (Chem)
safety
|
74.80
|
01.08.2026 |
|
C-Eval
knowledge
|
84.40%
|
22.04.2026 |
|
WebArena-Verified
general_agent
|
48.80
|
18.08.2026 |
|
Agents' Last Exam
general_agent
|
10.60
|
18.08.2026 |
|
Lab Bench (ProtocolQA)
safety
|
69.10
|
01.08.2026 |
Citation
Citation
If you find our work helpful, feel free to give us a cite.
@misc{qwen3.6-27b,
    title  = {{Qwen3.6-27B}: Flagship-Level Coding in a {27B} Dense Model},
    author = {{Qwen Team}},
    month  = {April},
    year   = {2026},
    url    = {https://qwen.ai/blog?id=qwen3.6-27b}
}
Model size
28B params
Tensor type
BF16
·
Best Practices
Best Practices
To achieve optimal performance, we recommend the following settings:
-
Sampling Parameters:
- We suggest using the following sets of sampling parameters depending on the mode and task type:
- Thinking mode for general tasks:
temperature=1.0,top_p=0.95,top_k=20,min_p=0.0,presence_penalty=0.0,repetition_penalty=1.0 - Thinking mode for precise coding tasks (e.g., WebDev):
temperature=0.6,top_p=0.95,top_k=20,min_p=0.0,presence_penalty=0.0,repetition_penalty=1.0 - Instruct (or non-thinking) mode:
temperature=0.7,top_p=0.80,top_k=20,min_p=0.0,presence_penalty=1.5,repetition_penalty=1.0
- Thinking mode for general tasks:
- For supported frameworks, you can adjust the
presence_penaltyparameter between 0 and 2 to reduce endless repetitions. However, using a higher value may occasionally result in language mixing and a slight decrease in model performance.
- We suggest using the following sets of sampling parameters depending on the mode and task type:
-
Adequate Output Length: We recommend using an output length of 32,768 tokens for most queries. For benchmarking on highly complex problems, such as those found in math and programming competitions, we suggest setting the max output length to 81,920 tokens. This provides the model with sufficient space to generate detailed and comprehensive responses, thereby enhancing its overall performance.
-
Standardize Output Format: We recommend using prompts to standardize model outputs when benchmarking.
- Math Problems: Include "Please reason step by step, and put your final answer within \boxed{}." in the prompt.
- Multiple-Choice Questions: Add the following JSON structure to the prompt to standardize responses: "Please show your choice in the
answerfield with only the choice letter, e.g.,"answer": "C"."
-
Long Video Understanding: To optimize inference efficiency for plain text and images, the
sizeparameter in the releasedvideo_preprocessor_config.jsonis conservatively configured. It is recommended to set thelongest_edgeparameter in the video_preprocessor_config file to 469,762,048 (corresponding to 224k video tokens) to enable higher frame-rate sampling for hour-scale videos and thereby achieve superior performance. For example,{"longest_edge": 469762048, "shortest_edge": 4096}Alternatively, override the default values via engine startup parameters. For implementation details, refer to: vLLM / SGLang.
Processing Ultra-Long Texts (1M context)
Processing Ultra-Long Texts
Qwen3.6 natively supports context lengths of up to 262,144 tokens. For long-horizon tasks where the total length (including both input and output) exceeds this limit, we recommend using RoPE scaling techniques to handle long texts effectively., e.g., YaRN.
YaRN is currently supported by several inference frameworks, e.g., transformers, vllm, ktransformers and sglang. In general, there are two approaches to enabling YaRN for supported frameworks:
-
Modifying the model configuration file: In the
config.jsonfile, change therope_parametersfields intext_configto:{ "mrope_interleaved": true, "mrope_section": [ 11, 11, 10 ], "rope_type": "yarn", "rope_theta": 10000000, "partial_rotary_factor": 0.25, "factor": 4.0, "original_max_position_embeddings": 262144, } -
Passing command line arguments:
For
vllm, you can useVLLM_ALLOW_LONG_MAX_MODEL_LEN=1 vllm serve ... --hf-overrides '{"text_config": {"rope_parameters": {"mrope_interleaved": true, "mrope_section": [11, 11, 10], "rope_type": "yarn", "rope_theta": 10000000, "partial_rotary_factor": 0.25, "factor": 4.0, "original_max_position_embeddings": 262144}}}' --max-model-len 1010000For
sglangandktransformers, you can useSGLANG_ALLOW_OVERWRITE_LONGER_CONTEXT_LEN=1 python -m sglang.launch_server ... --json-model-override-args '{"text_config": {"rope_parameters": {"mrope_interleaved": true, "mrope_section": [11, 11, 10], "rope_type": "yarn", "rope_theta": 10000000, "partial_rotary_factor": 0.25, "factor": 4.0, "original_max_position_embeddings": 262144}}}' --context-length 1010000
All the notable open-source frameworks implement static YaRN, which means the scaling factor remains constant regardless of input length, potentially impacting performance on shorter texts. We advise modifying the
rope_parametersconfiguration only when processing long contexts is required. It is also recommended to modify thefactoras needed. For example, if the typical context length for your application is 524,288 tokens, it would be better to setfactoras 2.0.
Agentic Usage (Qwen-Agent, Qwen Code)
Agentic Usage
Qwen3.6 excels in tool calling capabilities.
Qwen-Agent
We recommend using Qwen-Agent to quickly build Agent applications with Qwen3.6.
To define the available tools, you can use the MCP configuration file, use the integrated tool of Qwen-Agent, or integrate other tools by yourself.
import os
from qwen_agent.agents import Assistant

## Define LLM
## Using Alibaba Cloud Model Studio
llm_cfg = {
    # Use the OpenAI-compatible model service provided by DashScope:
    'model': 'qwen3.6-27b',
    'model_type': 'qwenvl_oai',
    'model_server': 'https://dashscope.aliyuncs.com/compatible-mode/v1',
    'api_key': os.getenv('DASHSCOPE_API_KEY'),

    'generate_cfg': {
        'use_raw_api': True,
        # When using Dash Scope OAI API, pass the parameter of whether to enable thinking mode in this way
        'extra_body': {
            'enable_thinking': True,
            'preserve_thinking': True,
        },
    },
}

## Using OpenAI-compatible API endpoint.
## functionality of the deployment frameworks and let Qwen-Agent automate the related operations.
##
## llm_cfg = {
##     # Use your own model service compatible with OpenAI API by vLLM/SGLang:
##     'model': 'Qwen/Qwen3.6-27B',
##     'model_type': 'qwenvl_oai',
##     'model_server': 'http://localhost:8000/v1',  # api_base
##     'api_key': 'EMPTY',
##
##     'generate_cfg': {
##         'use_raw_api': True,
##         # When using vLLM/SGLang OAI API, pass the parameter of whether to enable thinking mode in this way
##         'extra_body': {
##             'chat_template_kwargs': {'enable_thinking': True, 'preserve_thinking': True}
##         },
##     },
## }

## Define Tools
tools = [
    {'mcpServers': {  # You can specify the MCP configuration file
            "filesystem": {
                "command": "npx",
                "args": ["-y", "@modelcontextprotocol/server-filesystem", "/Users/xxxx/Desktop"]
            }
        }
    }
]

## Define Agent
bot = Assistant(llm=llm_cfg, function_list=tools)

## Streaming generation
messages = [{'role': 'user', 'content': 'Help me organize my desktop.'}]
for responses in bot.run(messages=messages):
    pass
print(responses)

## Streaming generation
messages = [{'role': 'user', 'content': 'Develop a dog website and save it on the desktop'}]
for responses in bot.run(messages=messages):
    pass
print(responses)
Qwen Code
Qwen Code is an open-source AI agent for the terminal, optimized for Qwen models. It helps you understand large codebases, automate tedious work, and ship faster.
For more information, please refer to Qwen Code.
Serving Qwen3.6 (vLLM/SGLang, thinking preservation)
Serving Qwen3.6
Qwen3.6 can be served via APIs with popular inference frameworks. In the following, we show example commands to launch OpenAI-Compatible API servers for Qwen3.6 models.
Inference efficiency and throughput vary significantly across frameworks. We recommend using the latest framework versions to ensure optimal performance and compatibility. For production workloads or high-throughput scenarios, dedicated serving engines such as SGLang, KTransformers or vLLM are strongly recommended.
The model has a default context length of 262,144 tokens. If you encounter out-of-memory (OOM) errors, consider reducing the context window. However, because Qwen3.6 leverages extended context for complex tasks, we advise maintaining a context length of at least 128K tokens to preserve thinking capabilities.
SGLang
SGLang is a fast serving framework for large language models and vision language models. sglang>=0.5.10 is recommended for Qwen3.6, which can be installed using the following command in a fresh environment:
uv pip install sglang[all]
See its documentation for more details.
The following will create API endpoints at http://localhost:8000/v1:
-
Standard Version: The following command can be used to create an API endpoint with maximum context length 262,144 tokens using tensor parallel on 8 GPUs.
python -m sglang.launch_server --model-path Qwen/Qwen3.6-27B --port 8000 --tp-size 8 --mem-fraction-static 0.8 --context-length 262144 --reasoning-parser qwen3 -
Tool Use: To support tool use, you can use the following command.
python -m sglang.launch_server --model-path Qwen/Qwen3.6-27B --port 8000 --tp-size 8 --mem-fraction-static 0.8 --context-length 262144 --reasoning-parser qwen3 --tool-call-parser qwen3_coder -
Multi-Token Prediction (MTP): The following command is recommended for MTP:
python -m sglang.launch_server --model-path Qwen/Qwen3.6-27B --port 8000 --tp-size 8 --mem-fraction-static 0.8 --context-length 262144 --reasoning-parser qwen3 --speculative-algo NEXTN --speculative-num-steps 3 --speculative-eagle-topk 1 --speculative-num-draft-tokens 4
For detailed deployment guide, see the SGLang Qwen3.5 Cookbook.
vLLM
vLLM is a high-throughput and memory-efficient inference and serving engine for LLMs. vllm>=0.19.0 is recommended for Qwen3.6, which can be installed using the following command in a fresh environment:
uv pip install vllm --torch-backend=auto
See its documentation for more details.
The following will create API endpoints at http://localhost:8000/v1:
-
Standard Version: The following command can be used to create an API endpoint with maximum context length 262,144 tokens using tensor parallel on 8 GPUs.
vllm serve Qwen/Qwen3.6-27B --port 8000 --tensor-parallel-size 8 --max-model-len 262144 --reasoning-parser qwen3 -
Tool Call: To support tool use, you can use the following command.
vllm serve Qwen/Qwen3.6-27B --port 8000 --tensor-parallel-size 8 --max-model-len 262144 --reasoning-parser qwen3 --enable-auto-tool-choice --tool-call-parser qwen3_coder -
Multi-Token Prediction (MTP): The following command is recommended for MTP:
vllm serve Qwen/Qwen3.6-27B --port 8000 --tensor-parallel-size 8 --max-model-len 262144 --reasoning-parser qwen3 --speculative-config '{"method":"qwen3_next_mtp","num_speculative_tokens":2}' -
Text-Only: The following command skips the vision encoder and multimodal profiling to free up memory for additional KV cache:
vllm serve Qwen/Qwen3.6-27B --port 8000 --tensor-parallel-size 8 --max-model-len 262144 --reasoning-parser qwen3 --language-model-only
For detailed deployment guide, see the vLLM Qwen3.5 Recipe.
KTransformers
KTransformers is a flexible framework for experiencing cutting-edge LLM inference optimizations with CPU-GPU heterogeneous computing. For running Qwen3.6 with KTransformers, see the KTransformers Deployment Guide.
Hugging Face Transformers
Hugging Face Transformers contains a lightweight server which can be used for quick testing and moderate load deployment. The latest transformers is required for Qwen3.6:
pip install "transformers[serving]"
See its documentation for more details. Please also make sure torchvision and pillow are installed.
Then, run transformers serve to launch a server with API endpoints at http://localhost:8000/v1; it will place the model on accelerators if available:
transformers serve Qwen/Qwen3.6-27B --port 8000 --continuous-batching
Using Qwen3.6 via the Chat Completions API
The chat completions API is accessible via standard HTTP requests or OpenAI SDKs. Here, we show examples using the OpenAI Python SDK.
Before starting, make sure it is installed and the API key and the API base URL is configured, e.g.:
pip install -U openai

## Set the following accordingly
export OPENAI_BASE_URL="http://localhost:8000/v1"
export OPENAI_API_KEY="EMPTY"
We recommend using the following set of sampling parameters for generation
- Thinking mode for general tasks:
temperature=1.0, top_p=0.95, top_k=20, min_p=0.0, presence_penalty=0.0, repetition_penalty=1.0- Thinking mode for precise coding tasks (e.g. WebDev):
temperature=0.6, top_p=0.95, top_k=20, min_p=0.0, presence_penalty=0.0, repetition_penalty=1.0- Instruct (or non-thinking) mode:
temperature=0.7, top_p=0.80, top_k=20, min_p=0.0, presence_penalty=1.5, repetition_penalty=1.0Please note that the support for sampling parameters varies according to inference frameworks.
Qwen3.6 models operate in thinking mode by default, generating thinking content signified by
<think>\n...</think>\n\nbefore producing the final responses. To disable thinking content and obtain direct response, refer to the examples here.
Text-Only Input
from openai import OpenAI
## Configured by environment variables
client = OpenAI()

messages = [
    {"role": "user", "content": "Type \"I love Qwen3.6\" backwards"},
]

chat_response = client.chat.completions.create(
    model="Qwen/Qwen3.6-27B",
    messages=messages,
    max_tokens=81920,
    temperature=1.0,
    top_p=0.95,
    presence_penalty=0.0,
    extra_body={
        "top_k": 20,
    },
)
print("Chat response:", chat_response)
Image Input
from openai import OpenAI
## Configured by environment variables
client = OpenAI()

messages = [
    {
        "role": "user",
        "content": [
            {
                "type": "image_url",
                "image_url": {
                    "url": "https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen3.5/demo/CI_Demo/mathv-1327.jpg"
                }
            },
            {

(section continues in the model card)
Quickstart
Quickstart
For streamlined integration, we recommend using Qwen3.6 via APIs. Below is a guide to use Qwen3.6 via OpenAI-compatible API.
Vision-Language Benchmark Results
Vision Language
| Qwen3.5-27B | Qwen3.5-397B-A17B | Gemma4-31B | Claude 4.5 Opus | Qwen3.6-35B-A3B | Qwen3.6-27B | |
|---|---|---|---|---|---|---|
| STEM & Puzzle | ||||||
| MMMU | 82.3 | 85.0 | 80.4 | 80.7 | 81.7 | 82.9 |
| MMMU-Pro | 75.0 | 79.0 | 76.9 | 70.6 | 75.3 | 75.8 |
| MathVista mini | 87.8 | -- | 79.3 | -- | 86.4 | 87.4 |
| DynaMath | 87.7 | 86.3 | 79.5 | 79.7 | 82.8 | 85.6 |
| VlmsAreBlind | 96.9 | -- | 87.2 | -- | 96.6 | 97.0 |
| General VQA | ||||||
| RealWorldQA | 83.7 | 83.9 | 72.3 | 77.0 | 85.3 | 84.1 |
| MMStar | 81.0 | 83.8 | 77.3 | 73.2 | 80.7 | 81.4 |
| MMBenchEN-DEV-v1.1 | 92.6 | -- | 90.9 | -- | 92.8 | 92.3 |
| SimpleVQA | 56.0 | 67.1 | 52.9 | 65.7 | 58.9 | 56.1 |
| Document Understanding | ||||||
| CharXiv RQ | 79.5 | 80.8 | 67.9 | 68.5 | 78.0 | 78.4 |
| CC-OCR | 81.0 | 82.0 | 75.7 | 76.9 | 81.9 | 81.2 |
| OCRBench | 89.4 | -- | 86.1 | -- | 90.0 | 89.4 |
| Spatial Intelligence | ||||||
| ERQA | 60.5 | 67.5 | 57.5 | 46.8 | 61.8 | 62.5 |
| CountBench | 97.8 | 97.2 | 96.1 | 90.6 | 96.1 | 97.8 |
| RefCOCO avg | 90.9 | 92.3 | -- | -- | 92.0 | 92.5 |
| EmbSpatialBench | 84.5 | -- | -- | -- | 84.3 | 84.6 |
| RefSpatialBench | 67.7 | -- | 4.7 | -- | 64.3 | 70.0 |
| Video Understanding | ||||||
| VideoMME(w sub.) | 87.0 | 87.5 | -- | 77.7 | 86.6 | 87.7 |
| VideoMMMU | 82.3 | 84.7 | 81.6 | 84.4 | 83.7 | 84.4 |
| MLVU | 85.9 | 86.7 | -- | 81.7 | 86.2 | 86.6 |
| MVBench | 74.6 | 77.6 | -- | 67.2 | 74.6 | 75.5 |
| Visual Agent | ||||||
| V* | 93.7 | 95.8 | -- | 67.0 | 90.1 | 94.7 |
| AndroidWorld | 64.2 | -- | -- | -- | -- | 70.3 |
* Empty cells (--) indicate scores not yet available or not applicable.
Language Benchmark Results
Language
| Qwen3.5-27B | Qwen3.5-397B-A17B | Gemma4-31B | Claude 4.5 Opus | Qwen3.6-35B-A3B | Qwen3.6-27B | |
|---|---|---|---|---|---|---|
| Coding Agent | ||||||
| SWE-bench Verified | 75.0 | 76.2 | 52.0 | 80.9 | 73.4 | 77.2 |
| SWE-bench Pro | 51.2 | 50.9 | 35.7 | 57.1 | 49.5 | 53.5 |
| SWE-bench Multilingual | 69.3 | 69.3 | 51.7 | 77.5 | 67.2 | 71.3 |
| Terminal-Bench 2.0 | 41.6 | 52.5 | 42.9 | 59.3 | 51.5 | 59.3 |
| SkillsBench Avg5 | 27.2 | 30.0 | 23.6 | 45.3 | 28.7 | 48.2 |
| QwenWebBench | 1068 | 1186 | 1197 | 1536 | 1397 | 1487 |
| NL2Repo | 27.3 | 32.2 | 15.5 | 43.2 | 29.4 | 36.2 |
| Claw-Eval Avg | 64.3 | 70.7 | 48.5 | 76.6 | 68.7 | 72.4 |
| Claw-Eval Pass^3 | 46.2 | 48.1 | 25.0 | 59.6 | 50.0 | 60.6 |
| QwenClawBench | 52.2 | 51.8 | 41.7 | 52.3 | 52.6 | 53.4 |
| Knowledge | ||||||
| MMLU-Pro | 86.1 | 87.8 | 85.2 | 89.5 | 85.2 | 86.2 |
| MMLU-Redux | 93.2 | 94.9 | 93.7 | 95.6 | 93.3 | 93.5 |
| SuperGPQA | 65.6 | 70.4 | 65.7 | 70.6 | 64.7 | 66.0 |
| C-Eval | 90.5 | 93.0 | 82.6 | 92.2 | 90.0 | 91.4 |
| STEM & Reasoning | ||||||
| GPQA Diamond | 85.5 | 88.4 | 84.3 | 87.0 | 86.0 | 87.8 |
| HLE | 24.3 | 28.7 | 19.5 | 30.8 | 21.4 | 24.0 |
| LiveCodeBench v6 | 80.7 | 83.6 | 80.0 | 84.8 | 80.4 | 83.9 |
| HMMT Feb 25 | 92.0 | 94.8 | 88.7 | 92.9 | 90.7 | 93.8 |
| HMMT Nov 25 | 89.8 | 92.7 | 87.5 | 93.3 | 89.1 | 90.7 |
| HMMT Feb 26 | 84.3 | 87.9 | 77.2 | 85.3 | 83.6 | 84.3 |
| IMOAnswerBench | 79.9 | 80.9 | 74.5 | 84.0 | 78.9 | 80.8 |
| AIME26 | 92.6 | 93.3 | 89.2 | 95.1 | 92.7 | 94.1 |
* SWE-Bench Series: Internal agent scaffold (bash + file-edit tools); temp=1.0, top_p=0.95, 200K context window. We correct some problematic tasks in the public set of SWE-bench Pro and evaluate all baselines on the refined benchmark.
* Terminal-Bench 2.0: Harbor/Terminus-2 harness; 3h timeout, 32 CPU/48 GB RAM; temp=1.0, top_p=0.95, top_k=20, max_tokens=80K, 256K ctx; avg of 5 runs.
* SkillsBench: Evaluated via OpenCode on 78 tasks (self-contained subset, excluding API-dependent tasks); avg of 5 runs.
* NL2Repo: Others are evaluated via Claude Code (temp=1.0, top_p=0.95, max_turns=900).
* QwenClawBench: A real-user-distribution Claw agent benchmark; temp=0.6, 256K ctx.
* QwenWebBench: An internal front-end code generation benchmark; bilingual (EN/CN), 7 categories (Web Design, Web Apps, Games, SVG, Data Visualization, Animation, and 3D); auto-render + multimodal judge (code/visual correctness); BT/Elo rating system.
* AIME 26: We use the full AIME 2026 (I & II), where the scores may differ from Qwen 3.5 notes.
Model Overview (architecture)
Model Overview
- Type: Causal Language Model with Vision Encoder
- Training Stage: Pre-training & Post-training
- Language Model
- Number of Parameters: 27B
- Hidden Dimension: 5120
- Token Embedding: 248320 (Padded)
- Number of Layers: 64
- Hidden Layout: 16 × (3 × (Gated DeltaNet → FFN) → 1 × (Gated Attention → FFN))
- Gated DeltaNet:
- Number of Linear Attention Heads: 48 for V and 16 for QK
- Head Dimension: 128
- Gated Attention:
- Number of Attention Heads: 24 for Q and 4 for KV
- Head Dimension: 256
- Rotary Position Embedding Dimension: 64
- Feed Forward Network:
- Intermediate Dimension: 17408
- LM Output: 248320 (Padded)
- MTP: trained with multi-steps
- Context Length: 262,144 natively and extensible up to 1,010,000 tokens.
Qwen3.6 Highlights (agentic coding, thinking preservation)
Qwen3.6 Highlights
This release delivers substantial upgrades, particularly in
- Agentic Coding: the model now handles frontend workflows and repository-level reasoning with greater fluency and precision.
- Thinking Preservation: we've introduced a new option to retain reasoning context from historical messages, streamlining iterative development and reducing overhead.
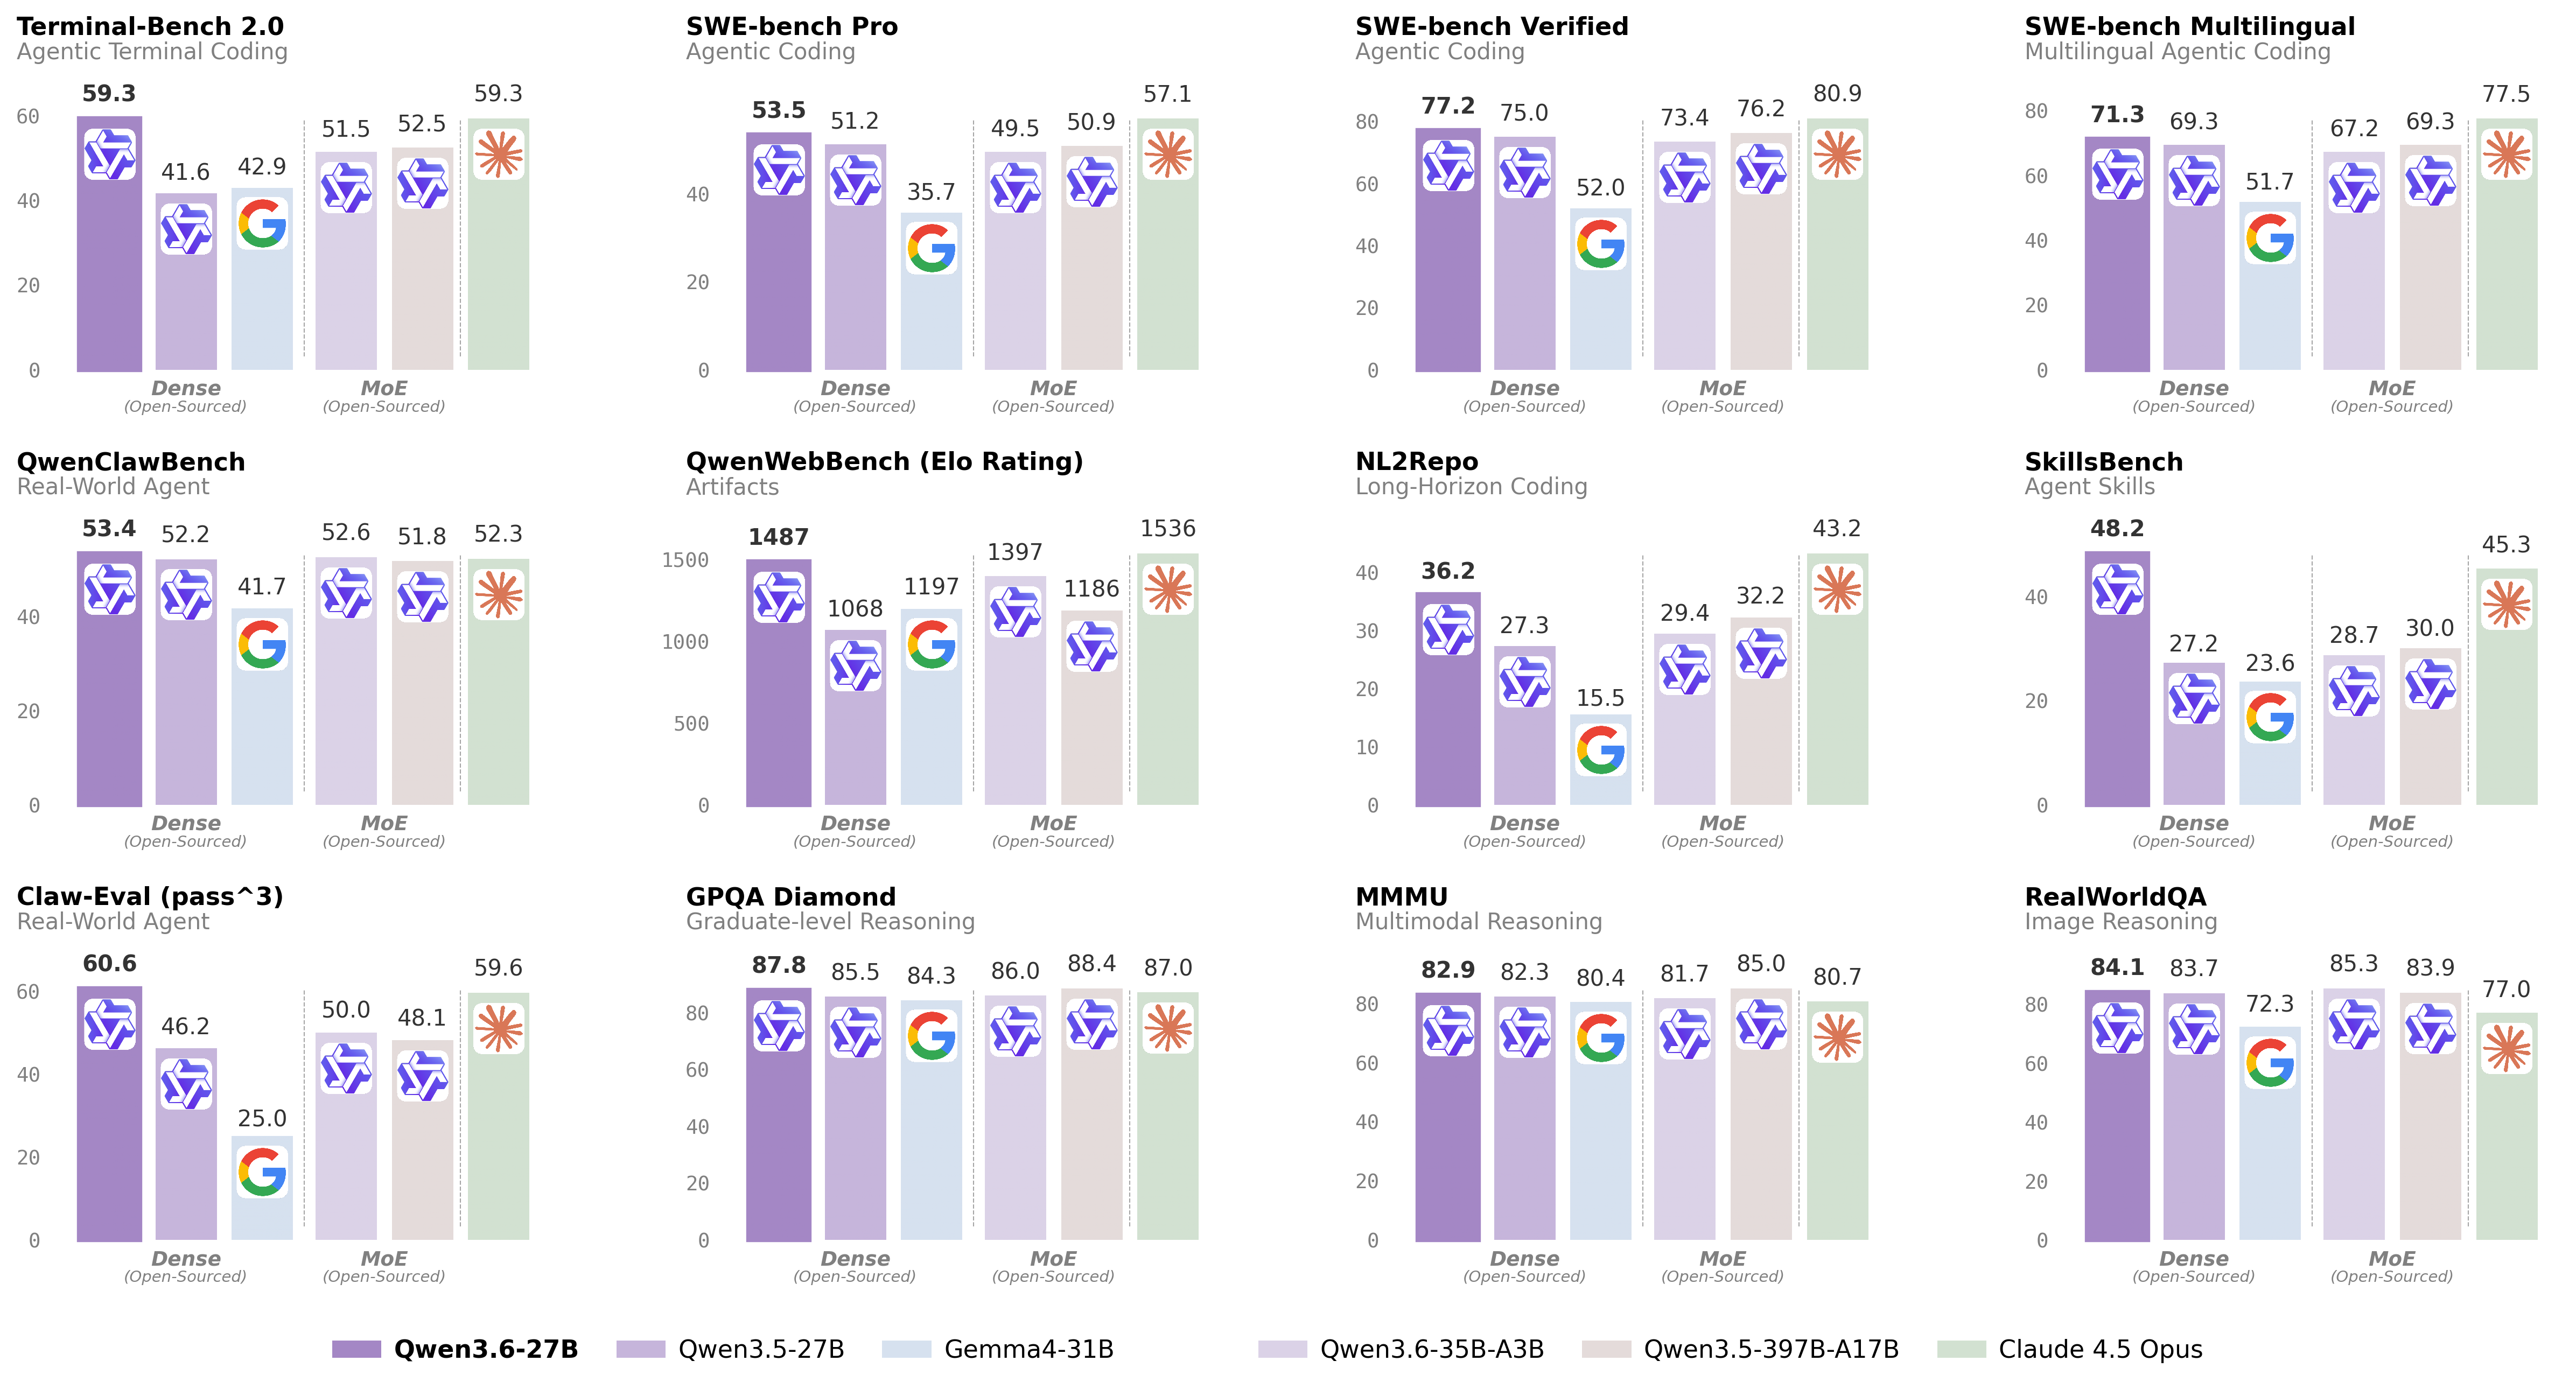
For more details, please refer to our blog post Qwen3.6-27B.
Architecture
- Attention
- Hybrid Attention (24:4)
- Layers
- 64
- Hidden size
- 5120
- Context
- 262K tokens
- Parameters
- 27000M
Source: Hugging Face config.json · Qwen3_5ForConditionalGeneration · exact layer pattern · model repo
248K
Training Pipeline
-
1
pretraining
Pre-training
Pre-training of the dense 27B language model with hybrid Gated DeltaNet + Gated Attention architecture and multi-token prediction (MTP).
-
2
other
Post-training
Post-training including thinking-mode alignment and introduction of Thinking Preservation (retaining reasoning traces across multi-turn conversations).
Training & Evaluation Datasets
| Name | Role | Size | Modalities | Collection |
|---|---|---|---|---|
| Qwen3.6 pre-training corpus (multimodal) | pretraining | — | — |
Linked Resources
Qwen3.6-27B Model Card (Hugging Face)
https://huggingface.co/Qwen/Qwen3.6-27B
Qwen3.6-27B: Flagship-Level Coding in a 27B Dense Model
https://qwen.ai/blog?id=qwen3.6-27b
QwenLM/Qwen-Agent
https://github.com/QwenLM/Qwen-Agent
QwenLM/qwen-code
https://github.com/QwenLM/qwen-code
Qwen Chat
https://chat.qwen.ai/
Qwen3.6 Collection
https://huggingface.co/collections/Qwen/qwen36
Citation (BibTeX) for Qwen3.6-27B
https://qwen.ai/blog?id=qwen3.6-27b
Trend Analysis
24h Change
+0.2%
7d Change
+1.9%
Current
101,994
downloads
-0.6%
downloads_all_time
+0.8%
likes
+0.0%
downloads
+0.0%
Usage & Social Metrics
| Source | Metric | Value | Period | Recorded |
|---|---|---|---|---|
| ollama | downloads | 6,300,000 pulls | daily | 01.09.2026 |
| huggingface | downloads_all_time | 25,011,211 | daily | 01.09.2026 |
| huggingface | followers | 101,994 | daily | 01.09.2026 |
| huggingface | likes | 2,284 | daily | 01.09.2026 |
| huggingface | downloads | 5,619,828 | daily | 01.09.2026 |
| ollama | downloads | 6,300,000 pulls | daily | 31.08.2026 |
| huggingface | downloads_all_time | 24,822,118 | daily | 31.08.2026 |
| huggingface | followers | 101,772 | daily | 31.08.2026 |
| huggingface | likes | 2,283 | daily | 31.08.2026 |
| huggingface | downloads | 5,651,249 | daily | 31.08.2026 |
| ollama | downloads | 6,300,000 pulls | daily | 30.08.2026 |
| huggingface | downloads_all_time | 24,713,088 | daily | 30.08.2026 |
| huggingface | followers | 101,528 | daily | 30.08.2026 |
| huggingface | likes | 2,282 | daily | 30.08.2026 |
| huggingface | downloads | 5,769,310 | daily | 30.08.2026 |
| ollama | downloads | 6,300,000 pulls | daily | 29.08.2026 |
| huggingface | followers | 101,306 | daily | 29.08.2026 |
| huggingface | likes | 2,281 | daily | 29.08.2026 |
| huggingface | downloads | 5,745,593 | daily | 29.08.2026 |
| ollama | downloads | 6,200,000 pulls | daily | 28.08.2026 |
| huggingface | followers | 101,117 | daily | 28.08.2026 |
| huggingface | likes | 2,279 | daily | 28.08.2026 |
| huggingface | downloads | 5,699,905 | daily | 28.08.2026 |
| ollama | downloads | 6,200,000 pulls | daily | 27.08.2026 |
| huggingface | followers | 100,862 | daily | 27.08.2026 |
| huggingface | likes | 2,278 | daily | 27.08.2026 |
| huggingface | downloads | 5,988,990 | daily | 27.08.2026 |
| ollama | downloads | 6,200,000 pulls | daily | 26.08.2026 |
| huggingface | followers | 100,537 | daily | 26.08.2026 |
| huggingface | likes | 2,279 | daily | 26.08.2026 |
| huggingface | downloads | 6,205,057 | daily | 26.08.2026 |
| ollama | downloads | 6,200,000 pulls | daily | 25.08.2026 |
| huggingface | followers | 100,133 | daily | 25.08.2026 |
| huggingface | likes | 2,279 | daily | 25.08.2026 |
| huggingface | downloads | 6,270,956 | daily | 25.08.2026 |
| ollama | downloads | 6,100,000 pulls | daily | 24.08.2026 |
| huggingface | followers | 99,896 | daily | 24.08.2026 |
| huggingface | likes | 2,279 | daily | 24.08.2026 |
| huggingface | downloads | 6,338,852 | daily | 24.08.2026 |
| huggingface | followers | 99,669 | daily | 23.08.2026 |
| huggingface | likes | 2,279 | daily | 23.08.2026 |
| huggingface | downloads | 6,348,356 | daily | 23.08.2026 |
| huggingface | followers | 99,461 | daily | 22.08.2026 |
| huggingface | likes | 2,276 | daily | 22.08.2026 |
| huggingface | downloads | 6,448,837 | daily | 22.08.2026 |
| huggingface | followers | 99,274 | daily | 21.08.2026 |
| huggingface | likes | 2,277 | daily | 21.08.2026 |
| huggingface | downloads | 6,530,210 | daily | 21.08.2026 |
| huggingface | followers | 99,037 | daily | 20.08.2026 |
| huggingface | likes | 2,276 | daily | 20.08.2026 |