Parameters
30.5B total / 3.3B active
MoE: total / active
Architecture
Mixture-of-Experts Transformer with Thinking mode
Released
29.07.2025
License
Apache License 2.0
Input Modalities
Output Modalities
Context (native)
262,144 tokens
Context (extended)
1,000,000 tokens
About
Qwen3-30B-A3B-Thinking-2507 (Qwen/Qwen3-30B-A3B-Thinking-2507) is the July 2025 update of Qwen3-30B-A3B that scales the model's thinking capability: significantly improved reasoning (logic, math, science, coding, academic benchmarks), markedly better general capabilities (instruction following, tool usage, text generation, alignment), and enhanced 256K long-context understanding. It is a 30.5B-parameter (29.9B non-embedding) Mixture-of-Experts model with 3.3B activated per token, 48 layers, Grouped-Query Attention (GQA) with 32 Q / 4 KV heads, 128 experts with 8 activated, and a 262,144-token native context extensible to 1M via config_1m.json (length extrapolation + sparse attention, ~240GB total GPU memory) in the spirit of YaRN.
Built on the Qwen3 thinking-mode system, this version supports only thinking mode - enable_thinking is no longer required and the default chat template automatically includes </think>, so outputs normally end with </think> without an opening <think> tag. Thinking length is increased; Qwen recommends it for highly complex reasoning tasks. Pre-trained on ~36 trillion tokens across 119 languages; 4-stage post-training (CoT cold start, reasoning RL, thinking mode fusion, general RL). Released under Apache 2.0.
Training Data Pretrained on ~36 trillion tokens across 119 languages; 4-stage post-training: CoT cold start, reasoning RL, thinking mode fusion, general RL
Benchmark Scores
| Benchmark | Score | Date |
|---|---|---|
|
MMLU-Pro
knowledge
|
67.42%
|
31.07.2025 |
|
MMLU-Redux
knowledge
|
82.35%
|
31.07.2025 |
|
GPQA Diamond
stem_reasoning
|
60.48%
|
31.07.2025 |
|
SuperGPQA
knowledge
|
68.92%
|
31.07.2025 |
|
AIME 2025
stem_reasoning
|
88.08%
|
31.07.2025 |
|
HMMT Feb 25
stem_reasoning
|
48.00%
|
31.07.2025 |
|
LiveCodeBench v6
stem_reasoning
|
62.48%
|
31.07.2025 |
|
OJBench
stem_reasoning
|
33.04%
|
31.07.2025 |
|
IFEval
instruction_following
|
89.87%
|
31.07.2025 |
|
MMLU-ProX
multilingual
|
35.48%
|
31.07.2025 |
|
INCLUDE
multilingual
|
26.36%
|
31.07.2025 |
|
PolyMATH
multilingual
|
30.86%
|
31.07.2025 |
Model Tree, Spaces and Papers
Model tree for Qwen/Qwen3-30B-A3B-Thinking-2507
Adapters
Finetunes
Merges
Quantizations
Spaces using Qwen/Qwen3-30B-A3B-Thinking-2507 18
Collection including Qwen/Qwen3-30B-A3B-Thinking-2507
[
Qwen3
Collection
84 items • Updated Dec 31, 2025 • 1.86k
](https://huggingface.co/collections/Qwen/qwen3)
Papers for Qwen/Qwen3-30B-A3B-Thinking-2507
[
Qwen3 Technical Report
Paper • 2505.09388 • Published May 14, 2025 • 346
](https://huggingface.co/papers/2505.09388)
[
Qwen2.5-1M Technical Report
Paper • 2501.15383 • Published Jan 26, 2025 • 72
](https://huggingface.co/papers/2501.15383)
[
MInference 1.0: Accelerating Pre-filling for Long-Context LLMs via Dynamic Sparse Attention
Paper • 2407.02490 • Published Jul 2, 2024 • 26
](https://huggingface.co/papers/2407.02490)
[
RULER: What's the Real Context Size of Your Long-Context Language Models?
Paper • 2404.06654 • Published Apr 9, 2024 • 42
](https://huggingface.co/papers/2404.06654)
[
Training-Free Long-Context Scaling of Large Language Models
Paper • 2402.17463 • Published Feb 27, 2024 • 24
](https://huggingface.co/papers/2402.17463)
Citation
Citation
If you find our work helpful, feel free to give us a cite.
@misc{qwen3technicalreport,
      title={Qwen3 Technical Report},
      author={Qwen Team},
      year={2025},
      eprint={2505.09388},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2505.09388},
}
Model size
31B params
Tensor type
BF16
·
Best Practices
Best Practices
To achieve optimal performance, we recommend the following settings:
-
Sampling Parameters:
- We suggest using
Temperature=0.6,TopP=0.95,TopK=20, andMinP=0. - For supported frameworks, you can adjust the
presence_penaltyparameter between 0 and 2 to reduce endless repetitions. However, using a higher value may occasionally result in language mixing and a slight decrease in model performance.
- We suggest using
-
Adequate Output Length: We recommend using an output length of 32,768 tokens for most queries. For benchmarking on highly complex problems, such as those found in math and programming competitions, we suggest setting the max output length to 81,920 tokens. This provides the model with sufficient space to generate detailed and comprehensive responses, thereby enhancing its overall performance.
-
Standardize Output Format: We recommend using prompts to standardize model outputs when benchmarking.
- Math Problems: Include "Please reason step by step, and put your final answer within \boxed{}." in the prompt.
- Multiple-Choice Questions: Add the following JSON structure to the prompt to standardize responses: "Please show your choice in the
answerfield with only the choice letter, e.g.,"answer": "C"."
-
No Thinking Content in History: In multi-turn conversations, the historical model output should only include the final output part and does not need to include the thinking content. It is implemented in the provided chat template in Jinja2. However, for frameworks that do not directly use the Jinja2 chat template, it is up to the developers to ensure that the best practice is followed.
Processing Ultra-Long Texts + How to Enable 1M Context
Processing Ultra-Long Texts
To support ultra-long context processing (up to 1 million tokens), we integrate two key techniques:
- Dual Chunk Attention (DCA): A length extrapolation method that splits long sequences into manageable chunks while preserving global coherence.
- MInference: A sparse attention mechanism that reduces computational overhead by focusing on critical token interactions.
Together, these innovations significantly improve both generation quality and inference efficiency for sequences beyond 256K tokens. On sequences approaching 1M tokens, the system achieves up to a 3× speedup compared to standard attention implementations.
For full technical details, see the Qwen2.5-1M Technical Report.
How to Enable 1M Token Context
To effectively process a 1 million token context, users will require approximately 240 GB of total GPU memory. This accounts for model weights, KV-cache storage, and peak activation memory demands.
Step 1: Update Configuration File
Download the model and replace the content of your config.json with config_1m.json, which includes the config for length extrapolation and sparse attention.
export MODELNAME=Qwen3-30B-A3B-Thinking-2507
huggingface-cli download Qwen/${MODELNAME} --local-dir ${MODELNAME}
mv ${MODELNAME}/config.json ${MODELNAME}/config.json.bak
mv ${MODELNAME}/config_1m.json ${MODELNAME}/config.json
Step 2: Launch Model Server
After updating the config, proceed with either vLLM or SGLang for serving the model.
Option 1: Using vLLM
To run Qwen with 1M context support:
pip install -U vllm \
    --torch-backend=auto \
    --extra-index-url https://wheels.vllm.ai/nightly
Then launch the server with Dual Chunk Flash Attention enabled:
VLLM_ATTENTION_BACKEND=DUAL_CHUNK_FLASH_ATTN VLLM_USE_V1=0 \
vllm serve ./Qwen3-30B-A3B-Thinking-2507 \
  --tensor-parallel-size 4 \
  --max-model-len 1010000 \
  --enable-chunked-prefill \
  --max-num-batched-tokens 131072 \
  --enforce-eager \
  --max-num-seqs 1 \
  --gpu-memory-utilization 0.85 \
  --enable-reasoning --reasoning-parser deepseek_r1
Key Parameters
| Parameter | Purpose |
|---|---|
VLLM_ATTENTION_BACKEND=DUAL_CHUNK_FLASH_ATTN |
Enables the custom attention kernel for long-context efficiency |
--max-model-len 1010000 |
Sets maximum context length to ~1M tokens |
--enable-chunked-prefill |
Allows chunked prefill for very long inputs (avoids OOM) |
--max-num-batched-tokens 131072 |
Controls batch size during prefill; balances throughput and memory |
--enforce-eager |
Disables CUDA graph capture (required for dual chunk attention) |
--max-num-seqs 1 |
Limits concurrent sequences due to extreme memory usage |
--gpu-memory-utilization 0.85 |
Set the fraction of GPU memory to be used for the model executor |
Option 2: Using SGLang
First, clone and install the specialized branch:
git clone https://github.com/sgl-project/sglang.git
cd sglang
pip install -e "python[all]"
Launch the server with DCA support:
python3 -m sglang.launch_server \
    --model-path ./Qwen3-30B-A3B-Thinking-2507 \
    --context-length 1010000 \
    --mem-frac 0.75 \
    --attention-backend dual_chunk_flash_attn \
    --tp 4 \
    --chunked-prefill-size 131072 \
    --reasoning-parser deepseek-r1
Key Parameters
| Parameter | Purpose |
|---|---|
--attention-backend dual_chunk_flash_attn |
Activates Dual Chunk Flash Attention |
--context-length 1010000 |
Defines max input length |
--mem-frac 0.75 |
The fraction of the memory used for static allocation (model weights and KV cache memory pool). Use a smaller value if you see out-of-memory errors. |
--tp 4 |
Tensor parallelism size (matches model sharding) |
--chunked-prefill-size 131072 |
Prefill chunk size for handling long inputs without OOM |
Troubleshooting:
-
Encountering the error: "The model's max sequence length (xxxxx) is larger than the maximum number of tokens that can be stored in the KV cache." or "RuntimeError: Not enough memory. Please try to increase --mem-fraction-static."
The VRAM reserved for the KV cache is insufficient.
- vLLM: Consider reducing the
max_model_lenor increasing thetensor_parallel_sizeandgpu_memory_utilization. Alternatively, you can reducemax_num_batched_tokens, although this may significantly slow down inference. - SGLang: Consider reducing the
context-lengthor increasing thetpandmem-frac. Alternatively, you can reducechunked-prefill-size, although this may significantly slow down inference.
- vLLM: Consider reducing the
-
Encountering the error: "torch.OutOfMemoryError: CUDA out of memory."
The VRAM reserved for activation weights is insufficient. You can try lowering
gpu_memory_utilizationormem-frac, but be aware that this might reduce the VRAM available f
(section continues in the model card)
Agentic Use (Qwen-Agent)
Agentic Use
Qwen3 excels in tool calling capabilities. We recommend using Qwen-Agent to make the best use of agentic ability of Qwen3. Qwen-Agent encapsulates tool-calling templates and tool-calling parsers internally, greatly reducing coding complexity.
To define the available tools, you can use the MCP configuration file, use the integrated tool of Qwen-Agent, or integrate other tools by yourself.
from qwen_agent.agents import Assistant

## Define LLM
## Using Alibaba Cloud Model Studio
llm_cfg = {
    'model': 'qwen3-30b-a3b-thinking-2507',
    'model_type': 'qwen_dashscope',
}

## Using OpenAI-compatible API endpoint. It is recommended to disable the reasoning and the tool call parsing
## functionality of the deployment frameworks and let Qwen-Agent automate the related operations. For example,
## `VLLM_USE_MODELSCOPE=true vllm serve Qwen/Qwen3-30B-A3B-Thinking-2507 --served-model-name Qwen3-30B-A3B-Thinking-2507 --tensor-parallel-size 8 --max-model-len 262144`.
##
## llm_cfg = {
##     'model': 'Qwen3-30B-A3B-Thinking-2507',
##
##     # Use a custom endpoint compatible with OpenAI API:
##     'model_server': 'http://localhost:8000/v1',  # api_base without reasoning and tool call parsing
##     'api_key': 'EMPTY',
##     'generate_cfg': {
##         'thought_in_content': True,
##     },
## }

## Define Tools
tools = [
    {'mcpServers': {  # You can specify the MCP configuration file
            'time': {
                'command': 'uvx',
                'args': ['mcp-server-time', '--local-timezone=Asia/Shanghai']
            },
            "fetch": {
                "command": "uvx",
                "args": ["mcp-server-fetch"]
            }
        }
    },
  'code_interpreter',  # Built-in tools
]

## Define Agent
bot = Assistant(llm=llm_cfg, function_list=tools)

## Streaming generation
messages = [{'role': 'user', 'content': 'https://qwenlm.github.io/blog/ Introduce the latest developments of Qwen'}]
for responses in bot.run(messages=messages):
    pass
print(responses)
Quickstart (transformers, thinking content parsing)
Quickstart
The code of Qwen3-MoE has been in the latest Hugging Face transformers and we advise you to use the latest version of transformers.
With transformers<4.51.0, you will encounter the following error:
KeyError: 'qwen3_moe'
The following contains a code snippet illustrating how to use the model generate content based on given inputs.
from transformers import AutoModelForCausalLM, AutoTokenizer

model_name = "Qwen/Qwen3-30B-A3B-Thinking-2507"

## load the tokenizer and the model
tokenizer = AutoTokenizer.from_pretrained(model_name)
model = AutoModelForCausalLM.from_pretrained(
    model_name,
    torch_dtype="auto",
    device_map="auto"
)

## prepare the model input
prompt = "Give me a short introduction to large language model."
messages = [
    {"role": "user", "content": prompt}
]
text = tokenizer.apply_chat_template(
    messages,
    tokenize=False,
    add_generation_prompt=True,
)
model_inputs = tokenizer([text], return_tensors="pt").to(model.device)

## conduct text completion
generated_ids = model.generate(
    **model_inputs,
    max_new_tokens=32768
)
output_ids = generated_ids[0][len(model_inputs.input_ids[0]):].tolist()

## parsing thinking content
try:
    # rindex finding 151668 (</think>)
    index = len(output_ids) - output_ids[::-1].index(151668)
except ValueError:
    index = 0

thinking_content = tokenizer.decode(output_ids[:index], skip_special_tokens=True).strip("\n")
content = tokenizer.decode(output_ids[index:], skip_special_tokens=True).strip("\n")

print("thinking content:", thinking_content) # no opening <think> tag
print("content:", content)
For deployment, you can use sglang>=0.4.6.post1 or vllm>=0.8.5 or to create an OpenAI-compatible API endpoint:
-
SGLang:
python -m sglang.launch_server --model-path Qwen/Qwen3-30B-A3B-Thinking-2507 --context-length 262144 --reasoning-parser deepseek-r1 -
vLLM:
vllm serve Qwen/Qwen3-30B-A3B-Thinking-2507 --max-model-len 262144 --enable-reasoning --reasoning-parser deepseek_r1
Note: If you encounter out-of-memory (OOM) issues, you may consider reducing the context length to a smaller value. However, since the model may require longer token sequences for reasoning, we strongly recommend using a context length greater than 131,072 when possible.
For local use, applications such as Ollama, LMStudio, MLX-LM, llama.cpp, and KTransformers have also supported Qwen3.
Performance (benchmark results)
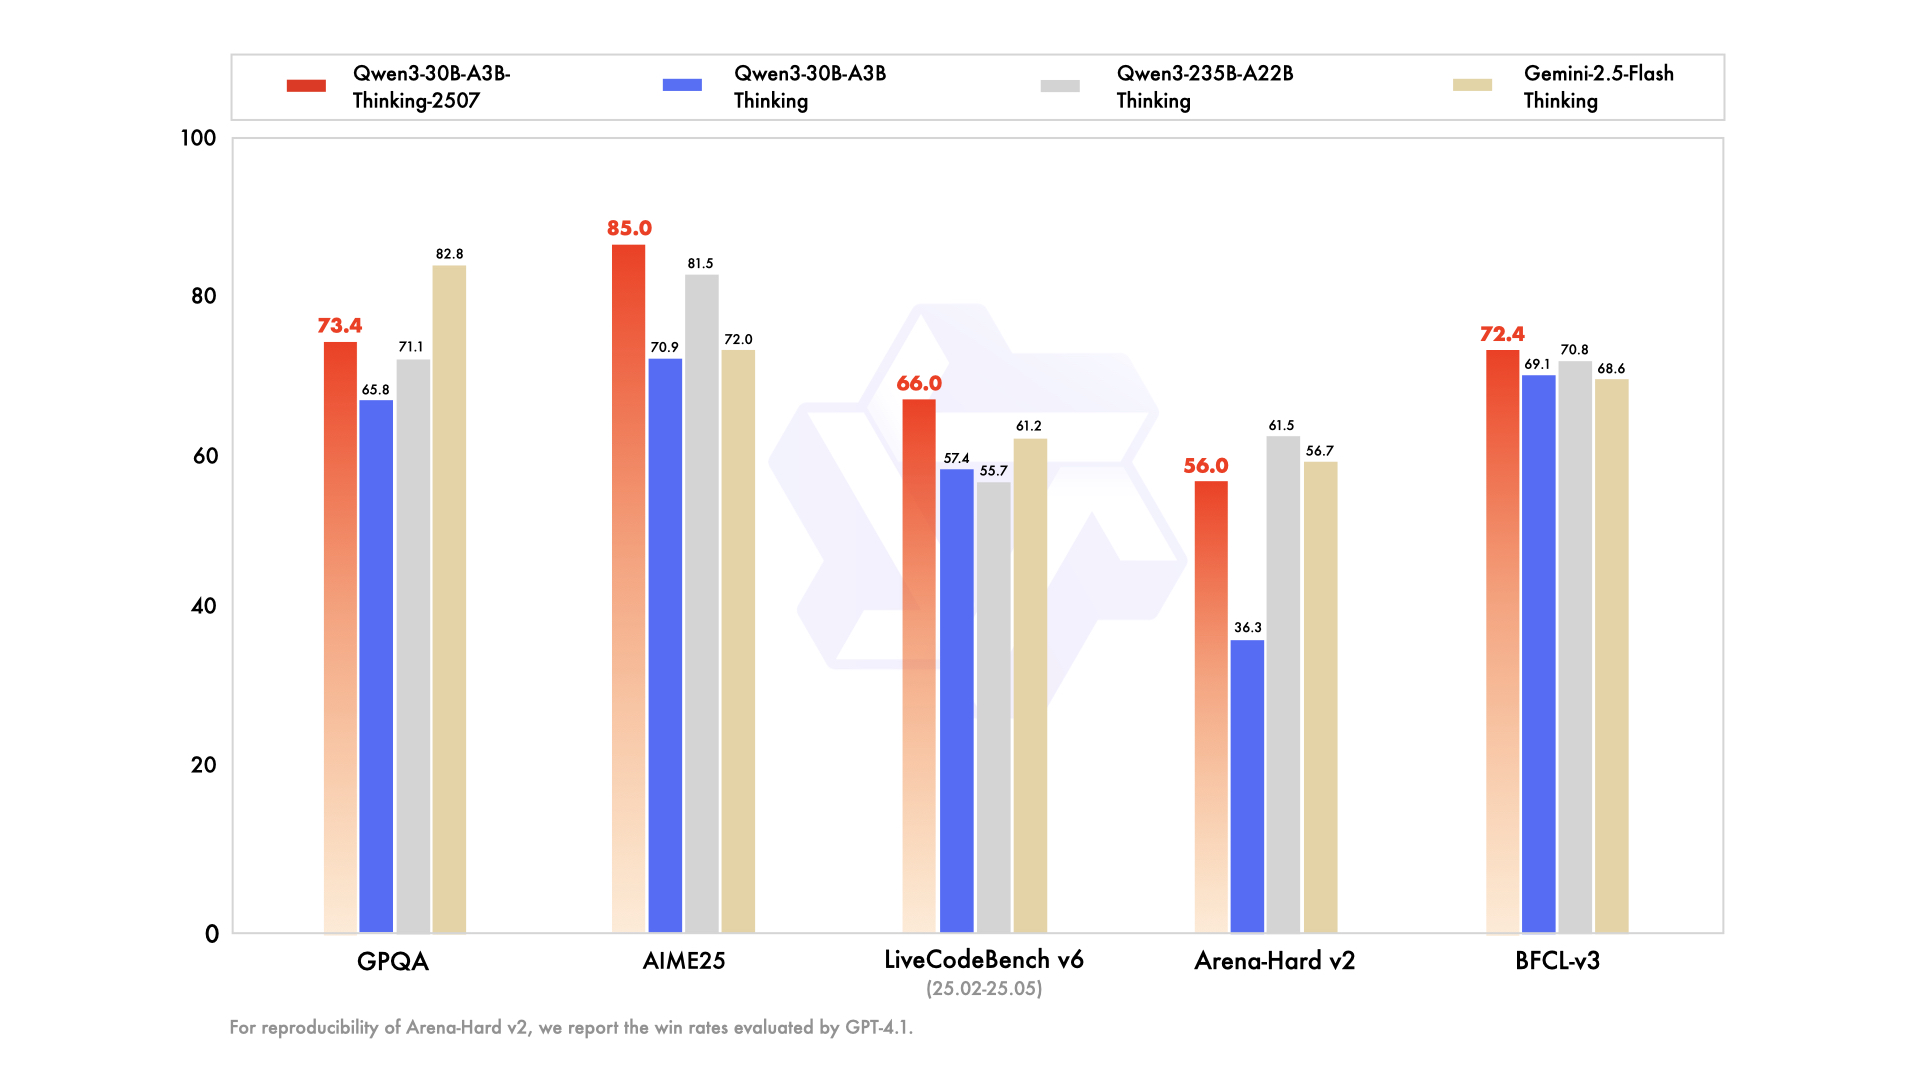
Performance
| Gemini2.5-Flash-Thinking | Qwen3-235B-A22B Thinking | Qwen3-30B-A3B Thinking | Qwen3-30B-A3B-Thinking-2507 | |
|---|---|---|---|---|
| Knowledge | ||||
| MMLU-Pro | 81.9 | 82.8 | 78.5 | 80.9 |
| MMLU-Redux | 92.1 | 92.7 | 89.5 | 91.4 |
| GPQA | 82.8 | 71.1 | 65.8 | 73.4 |
| SuperGPQA | 57.8 | 60.7 | 51.8 | 56.8 |
| Reasoning | ||||
| AIME25 | 72.0 | 81.5 | 70.9 | 85.0 |
| HMMT25 | 64.2 | 62.5 | 49.8 | 71.4 |
| LiveBench 20241125 | 74.3 | 77.1 | 74.3 | 76.8 |
| Coding | ||||
| LiveCodeBench v6 (25.02-25.05) | 61.2 | 55.7 | 57.4 | 66.0 |
| CFEval | 1995 | 2056 | 1940 | 2044 |
| OJBench | 23.5 | 25.6 | 20.7 | 25.1 |
| Alignment | ||||
| IFEval | 89.8 | 83.4 | 86.5 | 88.9 |
| Arena-Hard v2$ | 56.7 | 61.5 | 36.3 | 56.0 |
| Creative Writing v3 | 85.0 | 84.6 | 79.1 | 84.4 |
| WritingBench | 83.9 | 80.3 | 77.0 | 85.0 |
| Agent | ||||
| BFCL-v3 | 68.6 | 70.8 | 69.1 | 72.4 |
| TAU1-Retail | 65.2 | 54.8 | 61.7 | 67.8 |
| TAU1-Airline | 54.0 | 26.0 | 32.0 | 48.0 |
| TAU2-Retail | 66.7 | 40.4 | 34.2 | 58.8 |
| TAU2-Airline | 52.0 | 30.0 | 36.0 | 58.0 |
| TAU2-Telecom | 31.6 | 21.9 | 22.8 | 26.3 |
| Multilingualism | ||||
| MultiIF | 74.4 | 71.9 | 72.2 | 76.4 |
| MMLU-ProX | 80.2 | 80.0 | 73.1 | 76.4 |
| INCLUDE | 83.9 | 78.7 | 71.9 | 74.4 |
| PolyMATH | 49.8 | 54.7 | 46.1 | 52.6 |
$ For reproducibility, we report the win rates evaluated by GPT-4.1.
& For highly challenging tasks (including PolyMATH and all reasoning and coding tasks), we use an output length of 81,920 tokens. For all other tasks, we set the output length to 32,768.
Model Overview (thinking-only mode, template note)
Model Overview
Qwen3-30B-A3B-Thinking-2507 has the following features:
- Type: Causal Language Models
- Training Stage: Pretraining & Post-training
- Number of Parameters: 30.5B in total and 3.3B activated
- Number of Paramaters (Non-Embedding): 29.9B
- Number of Layers: 48
- Number of Attention Heads (GQA): 32 for Q and 4 for KV
- Number of Experts: 128
- Number of Activated Experts: 8
- Context Length: 262,144 natively.
NOTE: This model supports only thinking mode. Meanwhile, specifying enable_thinking=True is no longer required.
Additionally, to enforce model thinking, the default chat template automatically includes <think>. Therefore, it is normal for the model's output to contain only </think> without an explicit opening <think> tag.
For more details, including benchmark evaluation, hardware requirements, and inference performance, please refer to our blog, GitHub, and Documentation.
Highlights (thinking capability scale-up)
Highlights
Over the past three months, we have continued to scale the thinking capability of Qwen3-30B-A3B, improving both the quality and depth of reasoning. We are pleased to introduce Qwen3-30B-A3B-Thinking-2507, featuring the following key enhancements:
- Significantly improved performance on reasoning tasks, including logical reasoning, mathematics, science, coding, and academic benchmarks that typically require human expertise.
- Markedly better general capabilities, such as instruction following, tool usage, text generation, and alignment with human preferences.
- Enhanced 256K long-context understanding capabilities.
NOTE: This version has an increased thinking length. We strongly recommend its use in highly complex reasoning tasks.
Architecture
- Attention
- Grouped Query Attention (32:4)
- MoE
- 128 experts · top-8 per token
- Layers
- 48
- Hidden size
- 2048
- Context
- 262K tokens
- RoPE θ
- 10M
- Parameters
- 30500M
- Active params
- 3300M
Source: Hugging Face config.json · Qwen3MoeForCausalLM · model repo
Training Pipeline
-
1
pretraining
Three-Stage Pretraining (36T tokens, 119 languages)
Stage 1 (S1): Basic pretraining on over 30 trillion tokens with 4K context length. Stage 2 (S2): Improved dataset with increased proportion of knowledge-intensive data (STEM, coding, reasoning), 5 trillion additional tokens. Stage 3: Long-context extension to 32K tokens using high-quality long-context data. Total: ~36 trillion tokens across 119 languages.
-
2
sft
Long CoT Cold Start
Fine-tuned models using diverse long chain-of-thought (CoT) data covering mathematics, coding, logical reasoning, and STEM problems. This equipped the model with fundamental reasoning abilities.
-
3
rl
Reasoning-Based Reinforcement Learning
Scaled up computational resources for RL, utilizing rule-based rewards to enhance the model's exploration and exploitation capabilities for reasoning tasks.
-
4
sft
Thinking Mode Fusion
Integrated non-thinking capabilities into the thinking model by fine-tuning on a combination of long CoT data and instruction-tuning data generated by the enhanced thinking model from stage 2. This created a seamless blend of reasoning and quick response capabilities.
-
5
rl
General Reinforcement Learning
Applied RL across more than 20 general-domain tasks including instruction following, format following, and agent capabilities. This strengthened general capabilities and corrected undesired behaviors.
Training & Evaluation Datasets
| Name | Role | Size | Modalities | Collection |
|---|---|---|---|---|
| ~36T token pre-training corpus, 119 languages | pretraining | — | — |
Linked Resources
Qwen3 Technical Report
https://arxiv.org/abs/2505.09388
Qwen3 GitHub Repository
https://github.com/QwenLM/Qwen3
Qwen3: Think Deeper, Act Faster
https://qwenlm.github.io/blog/qwen3/
Qwen3 Documentation
https://qwen.readthedocs.io/en/latest/
Qwen3 Demo Space
https://huggingface.co/spaces/Qwen/Qwen3-Demo
Qwen Discord
https://discord.gg/yPEP2vHTu4
Qwen Chat
https://chat.qwen.ai/
Qwen3 Technical Report (BibTeX)
https://arxiv.org/abs/2505.09388
Trend Analysis
24h Change
+0.2%
7d Change
+1.9%
Current
101,994
likes
+0.1%
downloads
+0.0%
downloads_all_time
+0.3%
downloads
+0.3%
Usage & Social Metrics
| Source | Metric | Value | Period | Recorded |
|---|---|---|---|---|
| ollama | downloads | 36,000,000 pulls | daily | 01.09.2026 |
| huggingface | downloads_all_time | 20,126,396 | daily | 01.09.2026 |
| huggingface | followers | 101,994 | daily | 01.09.2026 |
| huggingface | likes | 931 | daily | 01.09.2026 |
| huggingface | downloads | 2,375,624 | daily | 01.09.2026 |
| ollama | downloads | 35,900,000 pulls | daily | 31.08.2026 |
| huggingface | downloads_all_time | 20,067,041 | daily | 31.08.2026 |
| huggingface | followers | 101,772 | daily | 31.08.2026 |
| huggingface | likes | 930 | daily | 31.08.2026 |
| huggingface | downloads | 2,375,419 | daily | 31.08.2026 |
| ollama | downloads | 35,900,000 pulls | daily | 30.08.2026 |
| huggingface | downloads_all_time | 20,047,958 | daily | 30.08.2026 |
| huggingface | followers | 101,528 | daily | 30.08.2026 |
| huggingface | likes | 929 | daily | 30.08.2026 |
| huggingface | downloads | 2,426,927 | daily | 30.08.2026 |
| ollama | downloads | 35,800,000 pulls | daily | 29.08.2026 |
| huggingface | followers | 101,306 | daily | 29.08.2026 |
| huggingface | likes | 929 | daily | 29.08.2026 |
| huggingface | downloads | 2,426,929 | daily | 29.08.2026 |
| ollama | downloads | 35,700,000 pulls | daily | 28.08.2026 |
| huggingface | followers | 101,117 | daily | 28.08.2026 |
| huggingface | likes | 929 | daily | 28.08.2026 |
| huggingface | downloads | 2,387,308 | daily | 28.08.2026 |
| ollama | downloads | 35,600,000 pulls | daily | 27.08.2026 |
| huggingface | followers | 100,862 | daily | 27.08.2026 |
| huggingface | likes | 929 | daily | 27.08.2026 |
| huggingface | downloads | 2,497,246 | daily | 27.08.2026 |
| ollama | downloads | 35,500,000 pulls | daily | 26.08.2026 |
| huggingface | followers | 100,537 | daily | 26.08.2026 |
| huggingface | likes | 927 | daily | 26.08.2026 |
| huggingface | downloads | 2,589,556 | daily | 26.08.2026 |
| ollama | downloads | 35,400,000 pulls | daily | 25.08.2026 |
| huggingface | followers | 100,133 | daily | 25.08.2026 |
| huggingface | likes | 927 | daily | 25.08.2026 |
| huggingface | downloads | 2,595,216 | daily | 25.08.2026 |
| ollama | downloads | 35,300,000 pulls | daily | 24.08.2026 |
| huggingface | followers | 99,896 | daily | 24.08.2026 |
| huggingface | likes | 926 | daily | 24.08.2026 |
| huggingface | downloads | 2,587,390 | daily | 24.08.2026 |